Resource
| Id | TF_ChIP-seq/ENCSR000BKO |
|---|---|
| Type | position_score |
| Version | 0 |
| Summary | TF_ChIP-seq ENCSR000BKO [biosample_summary="Homo sapiens K562" and target="SP1"] |
| Description |
status: released biological_replicates: Rep 1, Rep 2 summary: output_type: IDR thresholded peaks audit_internal_action: Released analysis {ENCAN454PMN|/analyses/ENCAN454PMN/} has in progress subobject quality standard {encode4-tf-chip|/quality-standards/encode4-tf-chip/} audit_internal_action: Released analysis {ENCAN454PMN|/analyses/ENCAN454PMN/} has in progress subobject document {ce94a34f-4090-49bc-87fb-242213021ece|/documents/ce94a34f-4090-49bc-87fb-242213021ece/} audit_warning: Processed alignments file {ENCFF617EYG|/files/ENCFF617EYG/} processed by ChIP-seq ENCODE4 v1.6.1 GRCh38 pipeline has 13657348 usable fragments. The minimum ENCODE standard for each replicate in a ChIP-seq experiment targeting SP1-human and investigated as a transcription factor is 10 million usable fragments. The recommended value is > 20 million, but > 10 million is acceptable. (See {ENCODE ChIP-seq data standards|/data-standards/chip-seq/} ) audit_warning: Processed alignments file {ENCFF716PNY|/files/ENCFF716PNY/} processed by ChIP-seq ENCODE4 v1.6.1 GRCh38 pipeline has 17621347 usable fragments. The minimum ENCODE standard for each replicate in a ChIP-seq experiment targeting SP1-human and investigated as a transcription factor is 10 million usable fragments. The recommended value is > 20 million, but > 10 million is acceptable. (See {ENCODE ChIP-seq data standards|/data-standards/chip-seq/} ) audit_warning: PBC1 (PCR Bottlenecking Coefficient 1, M1/M_distinct) is the ratio of the number of genomic locations where exactly one read maps uniquely (M1) to the number of genomic locations where some reads map (M_distinct). A PBC1 value in the range 0 - 0.5 is severe bottlenecking, 0.5 - 0.8 is moderate bottlenecking, 0.8 - 0.9 is mild bottlenecking, and > 0.9 is no bottlenecking. PBC1 value > 0.9 is recommended, but > 0.8 is acceptable. ENCODE processed alignments file {ENCFF617EYG|/files/ENCFF617EYG/} processed by ChIP-seq ENCODE4 v1.6.1 GRCh38 pipeline was generated from a library with PBC1 value of 0.90. audit_warning: PBC2 (PCR Bottlenecking Coefficient 2, M1/M2) is the ratio of the number of genomic locations where exactly one read maps uniquely (M1) to the number of genomic locations where two reads map uniquely (M2). A PBC2 value in the range 0 - 1 is severe bottlenecking, 1 - 3 is moderate bottlenecking, 3 - 10 is mild bottlenecking, > 10 is no bottlenecking. PBC2 value > 10 is recommended, but > 3 is acceptable. ENCODE processed alignments file {ENCFF617EYG|/files/ENCFF617EYG/} processed by ChIP-seq ENCODE4 v1.6.1 GRCh38 pipeline was generated from a library with PBC2 value of 9.41. audit_warning: Replicate concordance in ChIP-seq experiments is measured by calculating IDR values (Irreproducible Discovery Rate). ENCODE processed IDR thresholded peaks files {ENCFF171NEU|/files/ENCFF171NEU/} processed by ChIP-seq ENCODE4 v1.6.1 GRCh38 pipeline have a rescue ratio of 1.16 and a self consistency ratio of 2.61. According to ENCODE standards, having both rescue ratio and self consistency ratio values < 2 is recommended, but having only one of the ratio values < 2 is acceptable. |
| Labels |
|
Scores (1)
| ID | Type | Default annotation | Description | Histogram | Range | Summary |
|---|---|---|---|---|---|---|
| TF_ChIP-seq_ENCSR000BKO | float |
TF_ChIP-seq_ENCSR000BKO |
TF_ChIP-seq ENCSR000BKO [biosample_summary="Homo sapiens K562" and target="SP1"]
|
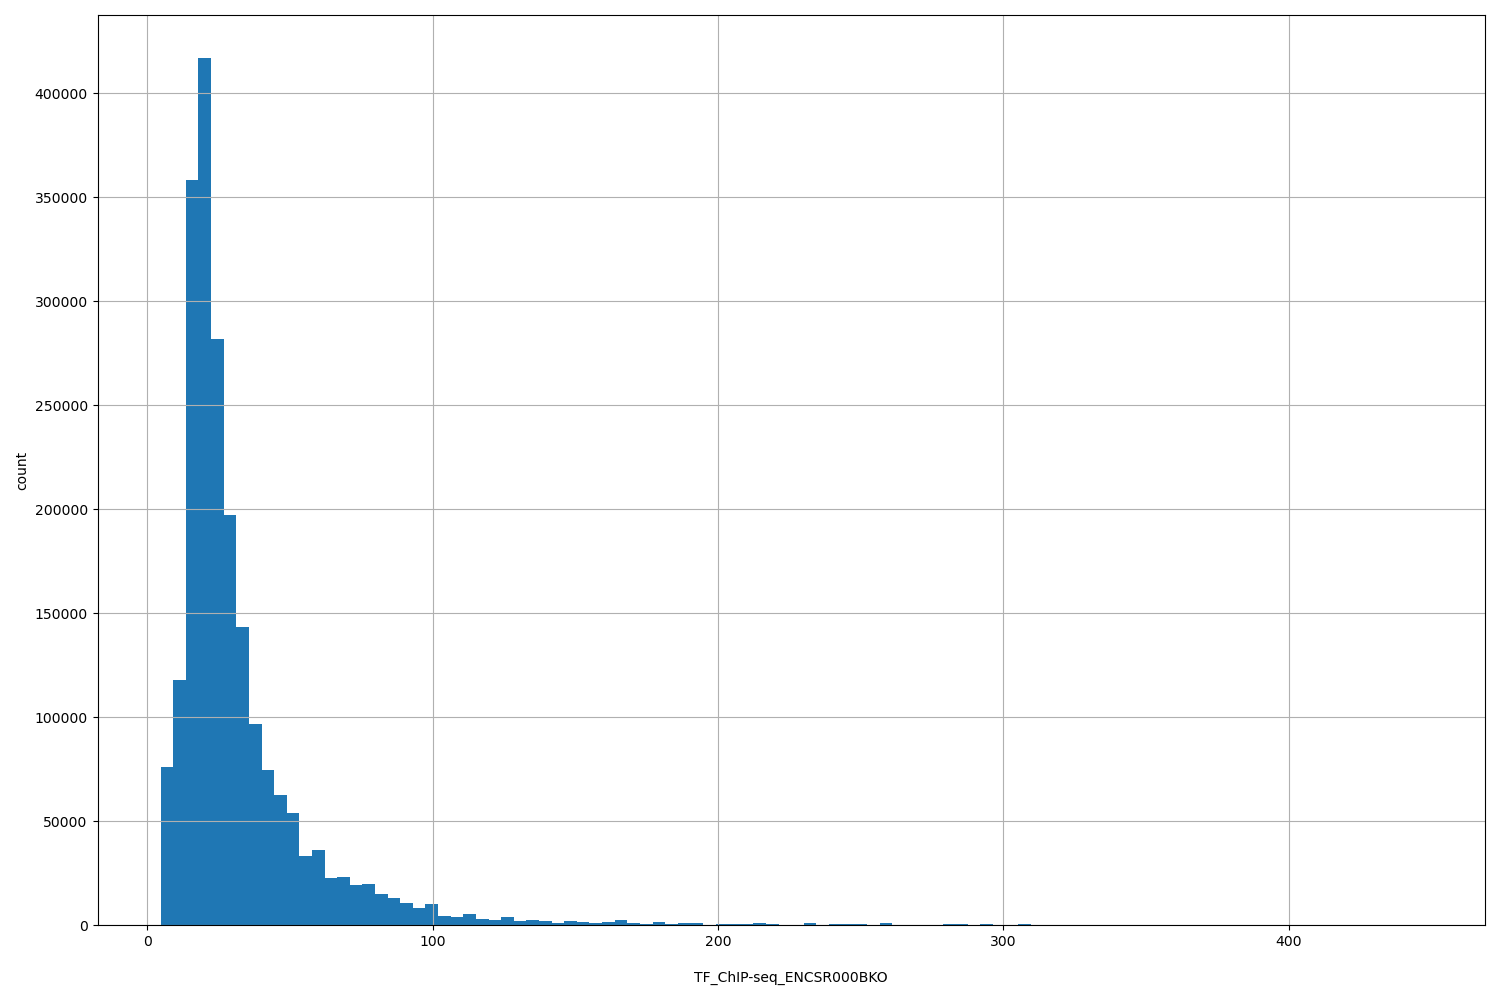 |
[4.71, 447] |
|
n counts base pairs; sd is the population standard deviation.
Coverage
| Chromosome | Covered positions | Covered % | Segments |
|---|---|---|---|
| all chromosomes | 2154594 | 0.07% | 8251 |
| chr1 | 291040 | 0.12% | 1125 |
| chr2 | 124286 | 0.05% | 476 |
| chr3 | 99393 | 0.05% | 382 |
| chr4 | 60392 | 0.03% | 223 |
| chr5 | 88082 | 0.05% | 345 |
| chr6 | 159161 | 0.09% | 613 |
| chr7 | 134230 | 0.08% | 513 |
| chr8 | 68805 | 0.05% | 267 |
| chr9 | 66806 | 0.05% | 253 |
| chr10 | 81838 | 0.06% | 312 |
| chr11 | 115748 | 0.09% | 447 |
| chr12 | 104442 | 0.08% | 393 |
| chr13 | 25882 | 0.02% | 100 |
| chr14 | 37963 | 0.04% | 143 |
| chr15 | 61544 | 0.06% | 238 |
| chr16 | 101433 | 0.11% | 383 |
| chr17 | 132080 | 0.16% | 497 |
| chr18 | 22635 | 0.03% | 82 |
| chr19 | 220573 | 0.38% | 854 |
| chr20 | 48488 | 0.08% | 185 |
| chr21 | 24033 | 0.05% | 94 |
| chr22 | 46391 | 0.09% | 180 |
| chrX | 39349 | 0.03% | 146 |
| 3343 contigs with no values (186304500 bp) | 0 | 0.00% | 0 |
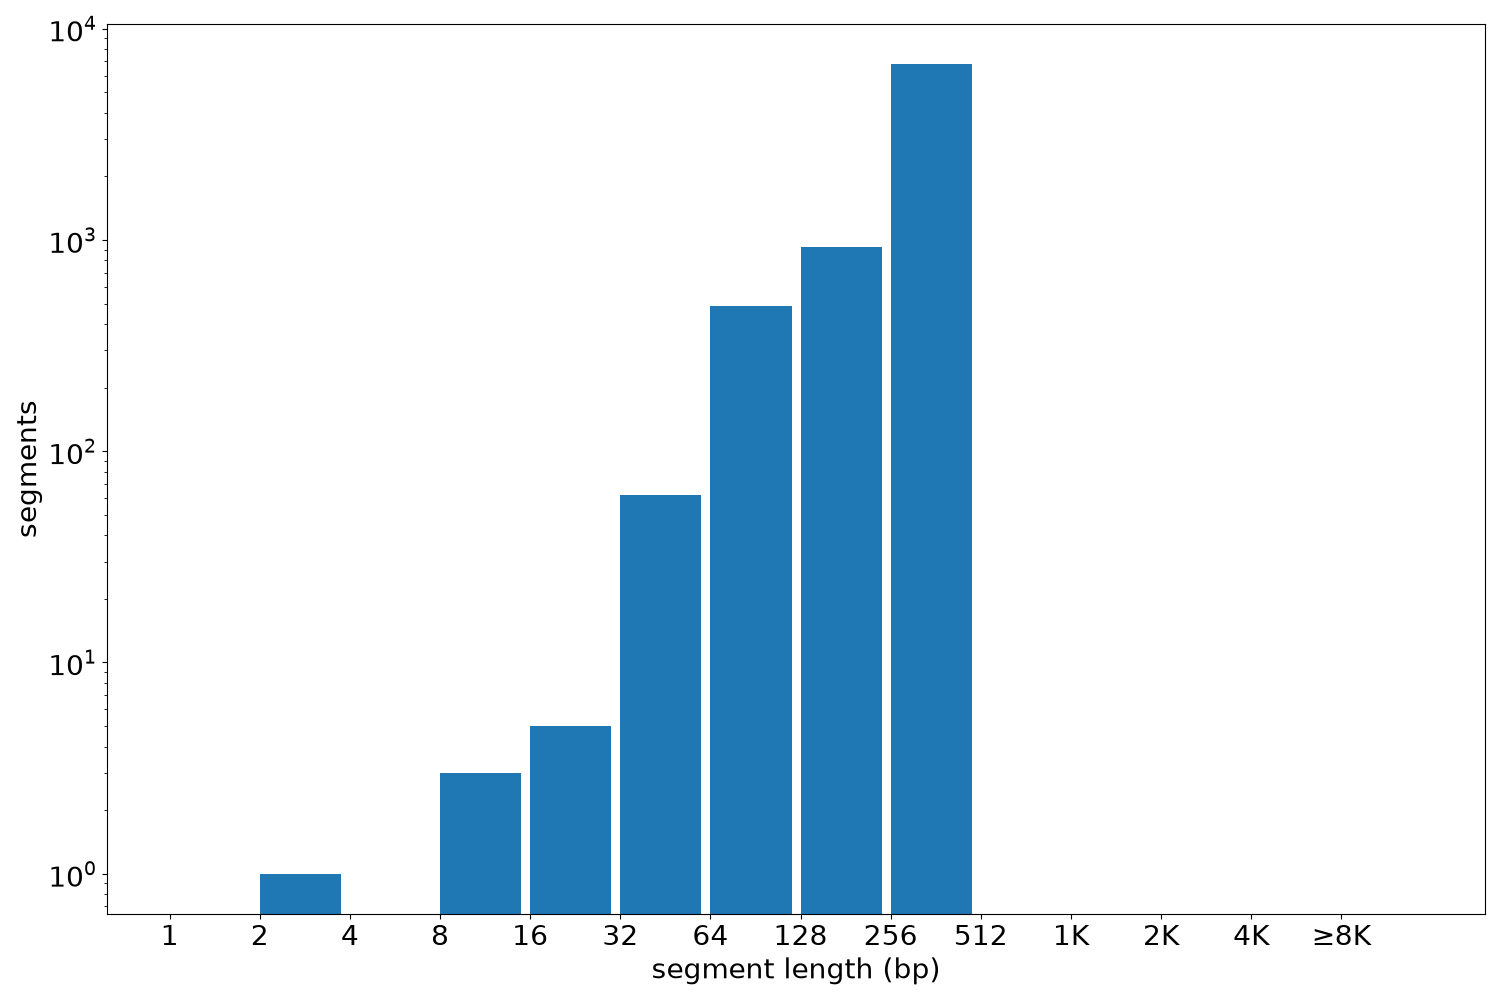
Segment lengths
| segments | min | max | mean | median | |
|---|---|---|---|---|---|
| segments | 8251 | 2 | 475 | 261.13 | 284 |
Files
| Filename | Size | md5 |
|---|---|---|
| ENCFF171NEU.bed.gz | 139.55 KB | ed96812047e32cf031bf7a494bbcfc54 |
| ENCFF171NEU.tabix.bed.gz | 96.64 KB | 995bbf5aba28e9ee9db0a52a157eaf2b |
| ENCFF171NEU.tabix.bed.gz.tbi | 64.13 KB | e94475cadbf6c2c51448314f6262cee6 |
| genomic_resource.yaml | 4.41 KB | 9561abad6b8467106ff91d56d062bf5d |
| statistics/ |