Resource
| Id | Histone_ChIP-seq/ENCSR444TMC |
|---|---|
| Type | position_score |
| Version | 0 |
| Summary | Histone_ChIP-seq ENCSR444TMC [biosample_summary="Homo sapiens IMR-90" and target="H4K8ac"] |
| Description |
status: released biological_replicates: Rep 1, Rep 2 summary: output_type: pseudoreplicated peaks audit_internal_action: Released analysis {ENCAN470OGG|/analyses/ENCAN470OGG/} has in progress subobject quality standard {encode4-histone-chip|/quality-standards/encode4-histone-chip/} audit_internal_action: Released analysis {ENCAN470OGG|/analyses/ENCAN470OGG/} has in progress subobject document {c1f2884f-6467-4160-8c89-74cead7a89b6|/documents/c1f2884f-6467-4160-8c89-74cead7a89b6/} audit_warning: Processed alignments file {ENCFF131UOL|/files/ENCFF131UOL/} processed by ChIP-seq ENCODE4 v1.6.1 GRCh38 pipeline has 14420466 usable fragments. The minimum ENCODE standard for each replicate in a ChIP-seq experiment targeting H4K8ac-human and investigated as a transcription factor is 10 million usable fragments. The recommended value is > 20 million, but > 10 million is acceptable. (See {ENCODE ChIP-seq data standards|/data-standards/chip-seq/} ) |
| Labels |
|
Scores (1)
| ID | Type | Default annotation | Description | Histogram | Range | Summary |
|---|---|---|---|---|---|---|
| Histone_ChIP-seq_ENCSR444TMC | float |
Histone_ChIP-seq_ENCSR444TMC |
Histone_ChIP-seq ENCSR444TMC [biosample_summary="Homo sapiens IMR-90" and target="H4K8ac"]
|
 |
[1.7, 50.1] |
|
n counts base pairs; sd is the population standard deviation.
Coverage
| Chromosome | Covered positions | Covered % | Segments |
|---|---|---|---|
| all chromosomes | 81056721 | 2.52% | 169089 |
| chr1 | 7306813 | 2.93% | 14988 |
| chr2 | 7223438 | 2.98% | 14926 |
| chr3 | 5186931 | 2.62% | 10997 |
| chr4 | 3599312 | 1.89% | 8444 |
| chr5 | 4816771 | 2.65% | 10194 |
| chr6 | 4644251 | 2.72% | 10331 |
| chr7 | 3944468 | 2.48% | 8596 |
| chr8 | 3833056 | 2.64% | 8440 |
| chr9 | 3595620 | 2.60% | 7277 |
| chr10 | 3688537 | 2.76% | 7812 |
| chr11 | 4671365 | 3.46% | 9190 |
| chr12 | 4156856 | 3.12% | 8735 |
| chr13 | 2101596 | 1.84% | 4771 |
| chr14 | 2541305 | 2.37% | 5204 |
| chr15 | 3229433 | 3.17% | 6398 |
| chr16 | 2602425 | 2.88% | 4919 |
| chr17 | 3810023 | 4.58% | 7102 |
| chr18 | 1693113 | 2.11% | 3754 |
| chr19 | 2608315 | 4.45% | 5017 |
| chr20 | 2045753 | 3.17% | 4070 |
| chr21 | 1026477 | 2.20% | 2212 |
| chr22 | 1525587 | 3.00% | 2831 |
| chrX | 1205276 | 0.77% | 2881 |
| 3343 contigs with no values (186304500 bp) | 0 | 0.00% | 0 |
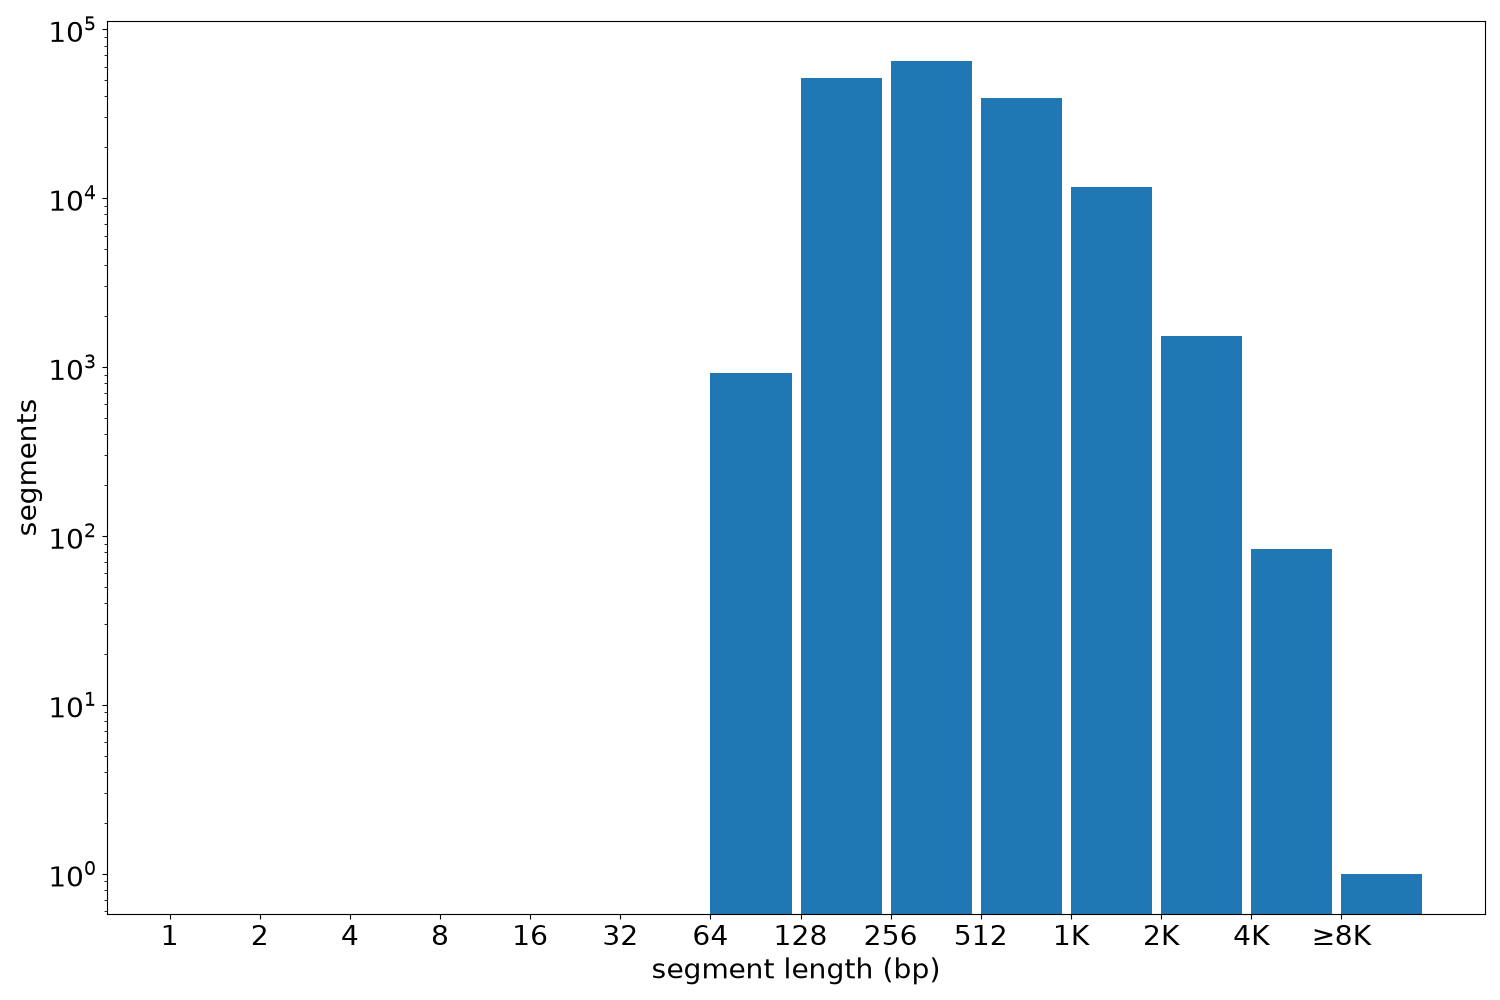
Segment lengths
| segments | min | max | mean | median | |
|---|---|---|---|---|---|
| segments | 169089 | 118 | 8260 | 479.37 | 352 |
Files
| Filename | Size | md5 |
|---|---|---|
| ENCFF339CWM.bed.gz | 4.09 MB | c0b44d9cdbcfd24126c8a050dcac18af |
| ENCFF339CWM.tabix.bed.gz | 1.73 MB | 7af5634ac9443531de7d5f1d2e2d2642 |
| ENCFF339CWM.tabix.bed.gz.tbi | 317.53 KB | 6211faa0b2b8c925aec4b412c282019d |
| genomic_resource.yaml | 2.09 KB | 6d34e262e3d596c437ee0b2f4235e3b8 |
| statistics/ |