Resource
| Id | Histone_ChIP-seq/ENCSR152YYY |
|---|---|
| Type | position_score |
| Version | 0 |
| Summary | Histone_ChIP-seq ENCSR152YYY [biosample_summary="Homo sapiens PC-9" and target="H4K20me1"] |
| Description |
status: released biological_replicates: Rep 1, Rep 2 summary: output_type: pseudoreplicated peaks audit_internal_action: Released analysis {ENCAN385UJT|/analyses/ENCAN385UJT/} has in progress subobject quality standard {encode4-histone-chip|/quality-standards/encode4-histone-chip/} audit_not_compliant: Processed alignments file {ENCFF287ZMV|/files/ENCFF287ZMV/} processed by ChIP-seq ENCODE4 v1.8.1 GRCh38 pipeline has 25360324 usable fragments. The minimum ENCODE standard for each replicate in a ChIP-seq experiment targeting H4K20me1-human and investigated as a broad histone mark is 20 million usable fragments. The recommended value is > 45 million, but > 35 million is acceptable. (See {ENCODE ChIP-seq data standards|/data-standards/chip-seq/}) audit_not_compliant: Processed alignments file {ENCFF854QXO|/files/ENCFF854QXO/} processed by ChIP-seq ENCODE4 v1.8.1 GRCh38 pipeline has 25823189 usable fragments. The minimum ENCODE standard for each replicate in a ChIP-seq experiment targeting H4K20me1-human and investigated as a broad histone mark is 20 million usable fragments. The recommended value is > 45 million, but > 35 million is acceptable. (See {ENCODE ChIP-seq data standards|/data-standards/chip-seq/}) |
| Labels |
|
Scores (1)
| ID | Type | Default annotation | Description | Histogram | Range | Summary |
|---|---|---|---|---|---|---|
| Histone_ChIP-seq_ENCSR152YYY | float |
Histone_ChIP-seq_ENCSR152YYY |
Histone_ChIP-seq ENCSR152YYY [biosample_summary="Homo sapiens PC-9" and target="H4K20me1"]
|
 |
[1.54, 16.4] |
|
n counts base pairs; sd is the population standard deviation.
Coverage
| Chromosome | Covered positions | Covered % | Segments |
|---|---|---|---|
| all chromosomes | 42198188 | 1.31% | 42584 |
| chr1 | 3561023 | 1.43% | 3704 |
| chr2 | 3928398 | 1.62% | 3949 |
| chr3 | 2683328 | 1.35% | 2741 |
| chr4 | 798308 | 0.42% | 872 |
| chr5 | 2390081 | 1.32% | 2406 |
| chr6 | 1807347 | 1.06% | 1832 |
| chr7 | 2972287 | 1.87% | 2912 |
| chr8 | 1659300 | 1.14% | 1718 |
| chr9 | 1445337 | 1.04% | 1525 |
| chr10 | 1113077 | 0.83% | 1272 |
| chr11 | 2330253 | 1.73% | 2487 |
| chr12 | 2127476 | 1.60% | 2151 |
| chr13 | 929152 | 0.81% | 1044 |
| chr14 | 1369652 | 1.28% | 1392 |
| chr15 | 782520 | 0.77% | 917 |
| chr16 | 2353123 | 2.60% | 2176 |
| chr17 | 2917869 | 3.50% | 2850 |
| chr18 | 534784 | 0.67% | 619 |
| chr19 | 2324816 | 3.97% | 1984 |
| chr20 | 1852427 | 2.87% | 1634 |
| chr21 | 204468 | 0.44% | 252 |
| chr22 | 1638855 | 3.22% | 1595 |
| chrX | 474307 | 0.30% | 552 |
| 3343 contigs with no values (186304500 bp) | 0 | 0.00% | 0 |
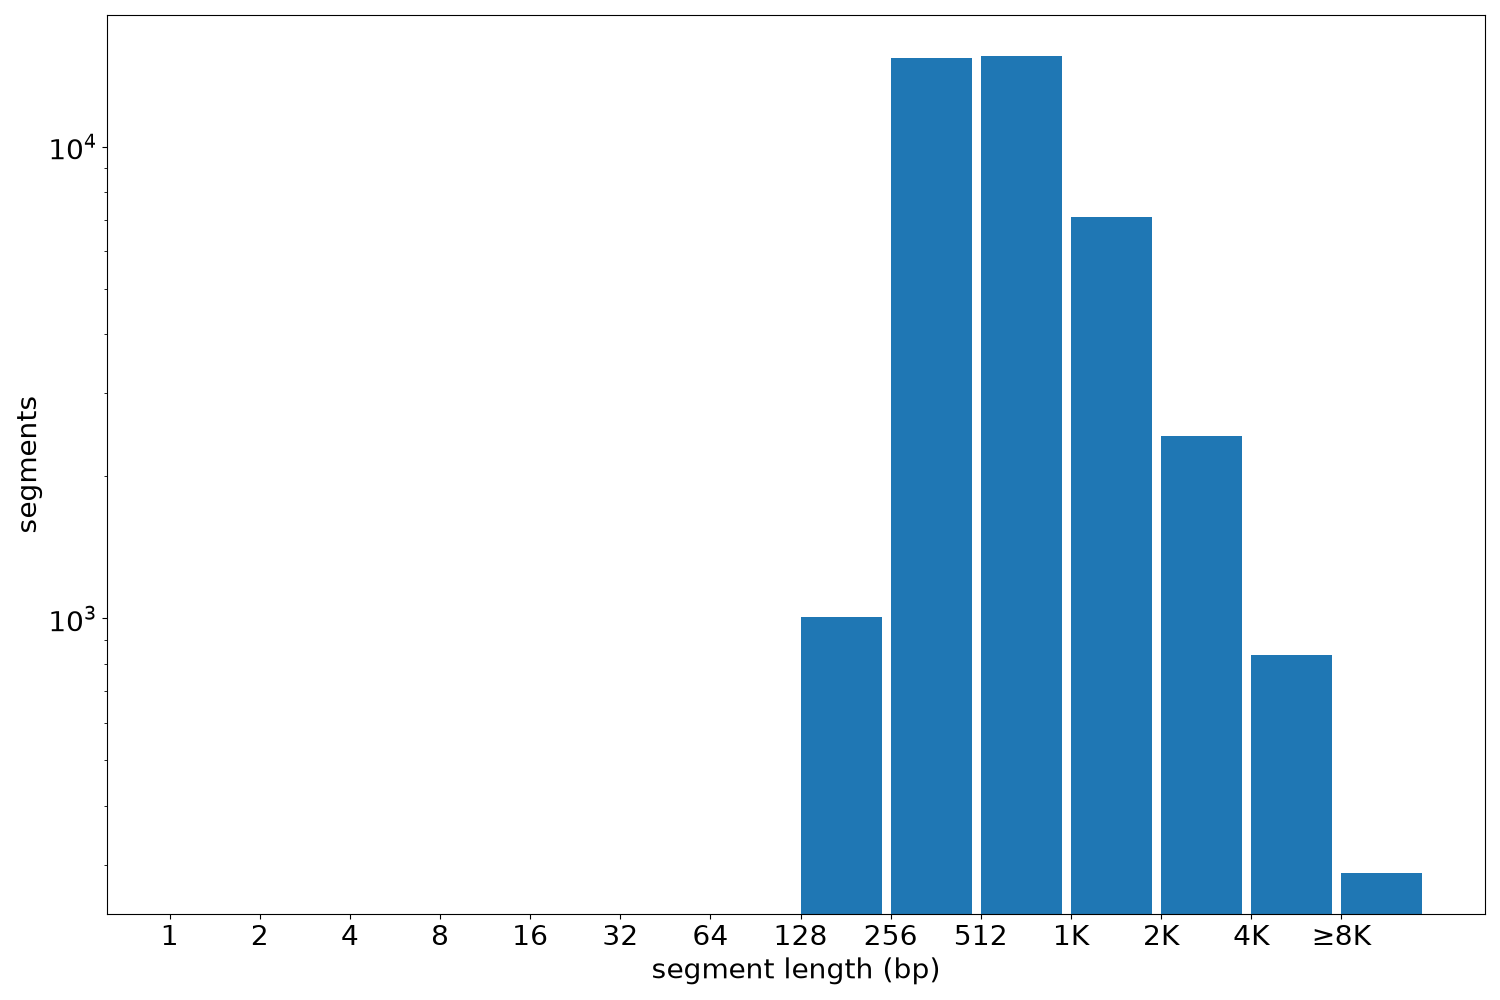
Segment lengths
| segments | min | max | mean | median | |
|---|---|---|---|---|---|
| segments | 42584 | 198 | 49037 | 990.94 | 615 |
Files
| Filename | Size | md5 |
|---|---|---|
| ENCFF299UST.bed.gz | 1006.47 KB | 36537de721c5a49cbbe9c69c659be86b |
| ENCFF299UST.tabix.bed.gz | 449.38 KB | 95afda94bec203abda7f962b1d8fcf0e |
| ENCFF299UST.tabix.bed.gz.tbi | 115.48 KB | bcddb36396148832c704967bedd5b2c5 |
| genomic_resource.yaml | 2.39 KB | ac9fde1336c334c5839de1938ab2fd28 |
| statistics/ |