Resource
| Id | Histone_ChIP-seq/ENCSR147GWR |
|---|---|
| Type | position_score |
| Version | 0 |
| Summary | Histone_ChIP-seq ENCSR147GWR [biosample_summary="Homo sapiens foreskin melanocyte male newborn" and target="H3K27me3"] |
| Description |
status: released biological_replicates: Rep 1 summary: male newborn output_type: pseudoreplicated peaks audit_internal_action: Released analysis {ENCAN052PPP|/analyses/ENCAN052PPP/} has in progress subobject quality standard {encode4-histone-chip|/quality-standards/encode4-histone-chip/} audit_warning: Processed redacted alignments file {ENCFF640JPZ|/files/ENCFF640JPZ/} processed by ChIP-seq ENCODE4 v1.7.0 GRCh38 pipeline has 38653854 usable fragments. The minimum ENCODE standard for each replicate in a ChIP-seq experiment targeting H3K27me3-human and investigated as a broad histone mark is 20 million usable fragments. The recommended value is > 45 million, but > 35 million is acceptable. (See {ENCODE ChIP-seq data standards|/data-standards/chip-seq/}) |
| Labels |
|
Scores (1)
| ID | Type | Default annotation | Description | Histogram | Range | Summary |
|---|---|---|---|---|---|---|
| Histone_ChIP-seq_ENCSR147GWR | float |
Histone_ChIP-seq_ENCSR147GWR |
Histone_ChIP-seq ENCSR147GWR [biosample_summary="Homo sapiens foreskin melanocyte male newborn" and target="H3K27me3"]
|
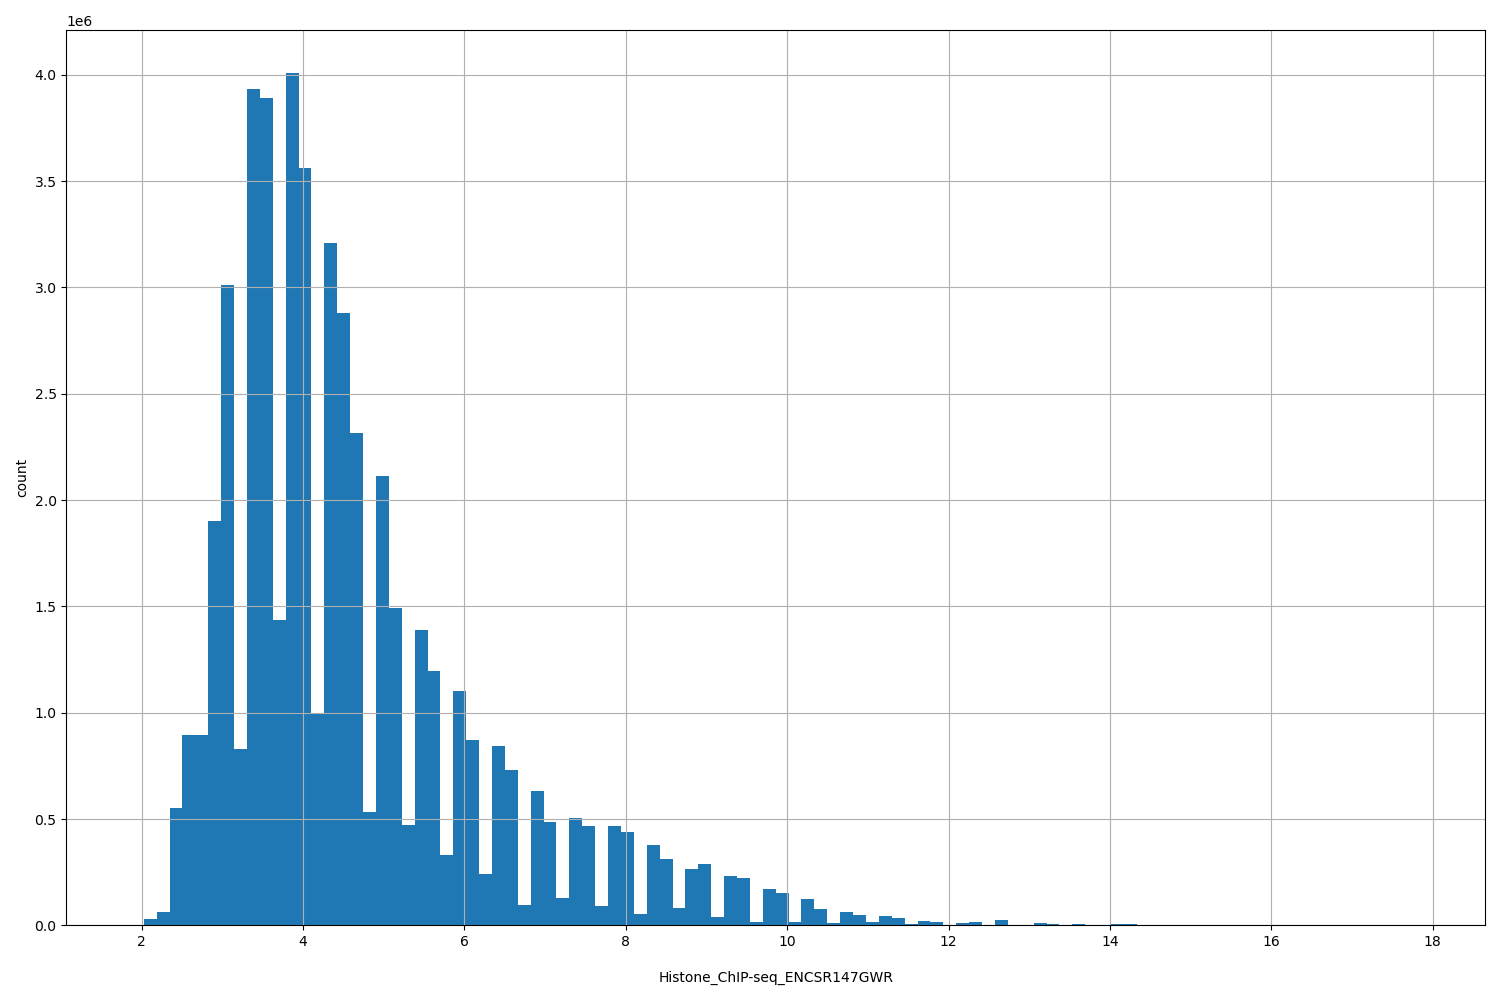 |
[1.87, 17.8] |
|
n counts base pairs; sd is the population standard deviation.
Coverage
| Chromosome | Covered positions | Covered % | Segments |
|---|---|---|---|
| all chromosomes | 51843766 | 1.61% | 117787 |
| chr1 | 5237653 | 2.10% | 11827 |
| chr2 | 3733012 | 1.54% | 8576 |
| chr3 | 2268728 | 1.14% | 5753 |
| chr4 | 1771056 | 0.93% | 3957 |
| chr5 | 2474705 | 1.36% | 5686 |
| chr6 | 2329733 | 1.36% | 5551 |
| chr7 | 2160886 | 1.36% | 4774 |
| chr8 | 2209697 | 1.52% | 5421 |
| chr9 | 2545491 | 1.84% | 5456 |
| chr10 | 3141665 | 2.35% | 7188 |
| chr11 | 4192426 | 3.10% | 9309 |
| chr12 | 2239800 | 1.68% | 5267 |
| chr13 | 912143 | 0.80% | 2187 |
| chr14 | 1511202 | 1.41% | 3498 |
| chr15 | 1695180 | 1.66% | 4085 |
| chr16 | 1841822 | 2.04% | 4095 |
| chr17 | 3135311 | 3.77% | 6488 |
| chr18 | 1270293 | 1.58% | 3179 |
| chr19 | 1895696 | 3.23% | 4014 |
| chr20 | 2322581 | 3.60% | 5114 |
| chr21 | 615539 | 1.32% | 1433 |
| chr22 | 2119723 | 4.17% | 4418 |
| chrX | 216894 | 0.14% | 504 |
| chrY | 2530 | <0.01% | 7 |
| 3342 contigs with no values (129077085 bp) | 0 | 0.00% | 0 |
Segment lengths
| segments | min | max | mean | median | |
|---|---|---|---|---|---|
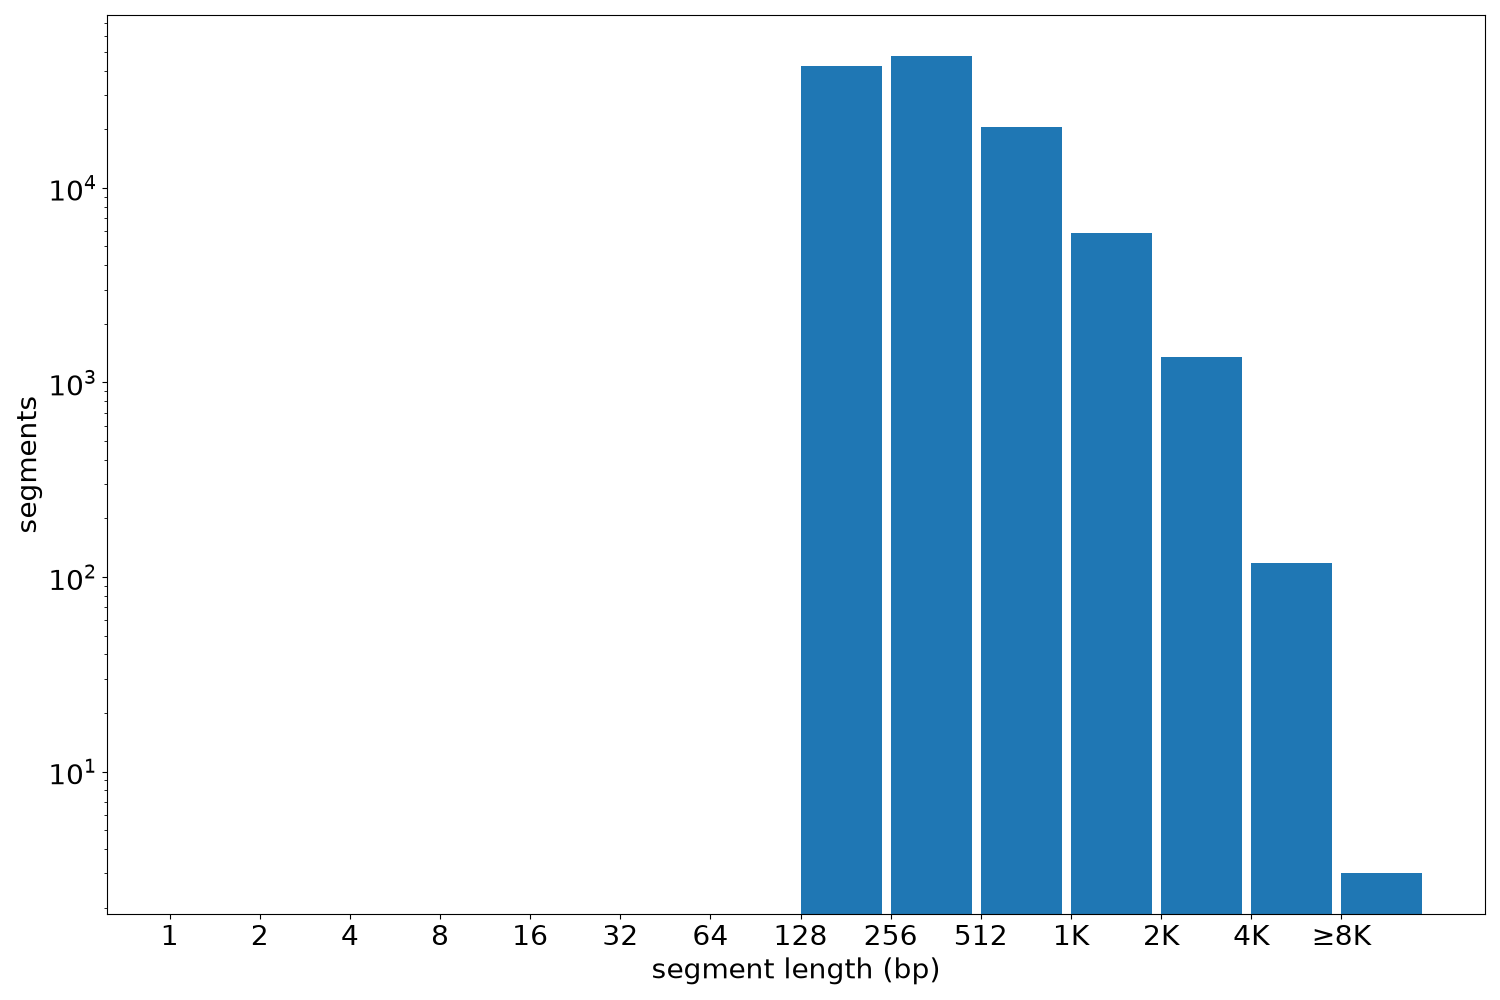
| segments | 117787 | 160 | 11398 | 440.15 | 312 |
Files
| Filename | Size | md5 |
|---|---|---|
| ENCFF250MQB.bed.gz | 1.91 MB | a13f697b12a045cccdfb6b97a3b8b323 |
| ENCFF250MQB.tabix.bed.gz | 1.03 MB | 1da07d621791281f83acdacc5773cf15 |
| ENCFF250MQB.tabix.bed.gz.tbi | 254.46 KB | 88f9f9591297d2875394646347f186fe |
| genomic_resource.yaml | 1.96 KB | e000670bb91e16c42b04c29f3b33c589 |
| statistics/ |