Resource
| Id | Histone_ChIP-seq/ENCSR000DXZ |
|---|---|
| Type | position_score |
| Version | 0 |
| Summary | Histone_ChIP-seq ENCSR000DXZ [biosample_summary="Homo sapiens WI38" and target="H3K4me3"] |
| Description |
status: released biological_replicates: Rep 1, Rep 2 summary: output_type: pseudoreplicated peaks audit_internal_action: Released analysis {ENCAN005BDH|/analyses/ENCAN005BDH/} has in progress subobject document {221e49d9-2be2-46c8-9e55-2b2f53ad8186|/documents/221e49d9-2be2-46c8-9e55-2b2f53ad8186/} audit_internal_action: Released analysis {ENCAN005BDH|/analyses/ENCAN005BDH/} has in progress subobject quality standard {encode4-histone-chip|/quality-standards/encode4-histone-chip/} audit_warning: Processed alignments file {ENCFF678NRT|/files/ENCFF678NRT/} processed by ChIP-seq ENCODE4 v1.5.1 GRCh38 pipeline has 12855195 usable fragments. The minimum ENCODE standard for each replicate in a ChIP-seq experiment targeting H3K4me3-human and investigated as a narrow histone mark is 10 million usable fragments. The recommended value is > 20 million, but > 10 million is acceptable. (See {ENCODE ChIP-seq data standards|/data-standards/chip-seq/}) audit_warning: Processed alignments file {ENCFF864WBR|/files/ENCFF864WBR/} processed by ChIP-seq ENCODE4 v1.5.1 GRCh38 pipeline has 13309353 usable fragments. The minimum ENCODE standard for each replicate in a ChIP-seq experiment targeting H3K4me3-human and investigated as a narrow histone mark is 10 million usable fragments. The recommended value is > 20 million, but > 10 million is acceptable. (See {ENCODE ChIP-seq data standards|/data-standards/chip-seq/}) audit_warning: PBC1 (PCR Bottlenecking Coefficient 1, M1/M_distinct) is the ratio of the number of genomic locations where exactly one read maps uniquely (M1) to the number of genomic locations where some reads map (M_distinct). A PBC1 value in the range 0 - 0.5 is severe bottlenecking, 0.5 - 0.8 is moderate bottlenecking, 0.8 - 0.9 is mild bottlenecking, and > 0.9 is no bottlenecking. PBC1 value > 0.9 is recommended, but > 0.8 is acceptable. ENCODE processed alignments file {ENCFF678NRT|/files/ENCFF678NRT/} processed by ChIP-seq ENCODE4 v1.5.1 GRCh38 pipeline was generated from a library with PBC1 value of 0.86. audit_warning: PBC2 (PCR Bottlenecking Coefficient 2, M1/M2) is the ratio of the number of genomic locations where exactly one read maps uniquely (M1) to the number of genomic locations where two reads map uniquely (M2). A PBC2 value in the range 0 - 1 is severe bottlenecking, 1 - 3 is moderate bottlenecking, 3 - 10 is mild bottlenecking, > 10 is no bottlenecking. PBC2 value > 10 is recommended, but > 3 is acceptable. ENCODE processed alignments file {ENCFF678NRT|/files/ENCFF678NRT/} processed by ChIP-seq ENCODE4 v1.5.1 GRCh38 pipeline was generated from a library with PBC2 value of 7.15. audit_warning: PBC1 (PCR Bottlenecking Coefficient 1, M1/M_distinct) is the ratio of the number of genomic locations where exactly one read maps uniquely (M1) to the number of genomic locations where some reads map (M_distinct). A PBC1 value in the range 0 - 0.5 is severe bottlenecking, 0.5 - 0.8 is moderate bottlenecking, 0.8 - 0.9 is mild bottlenecking, and > 0.9 is no bottlenecking. PBC1 value > 0.9 is recommended, but > 0.8 is acceptable. ENCODE processed alignments file {ENCFF864WBR|/files/ENCFF864WBR/} processed by ChIP-seq ENCODE4 v1.5.1 GRCh38 pipeline was generated from a library with PBC1 value of 0.88. audit_warning: PBC2 (PCR Bottlenecking Coefficient 2, M1/M2) is the ratio of the number of genomic locations where exactly one read maps uniquely (M1) to the number of genomic locations where two reads map uniquely (M2). A PBC2 value in the range 0 - 1 is severe bottlenecking, 1 - 3 is moderate bottlenecking, 3 - 10 is mild bottlenecking, > 10 is no bottlenecking. PBC2 value > 10 is recommended, but > 3 is acceptable. ENCODE processed alignments file {ENCFF864WBR|/files/ENCFF864WBR/} processed by ChIP-seq ENCODE4 v1.5.1 GRCh38 pipeline was generated from a library with PBC2 value of 8.72. |
| Labels |
|
Scores (1)
| ID | Type | Default annotation | Description | Histogram | Range | Summary |
|---|---|---|---|---|---|---|
| Histone_ChIP-seq_ENCSR000DXZ | float |
Histone_ChIP-seq_ENCSR000DXZ |
Histone_ChIP-seq ENCSR000DXZ [biosample_summary="Homo sapiens WI38" and target="H3K4me3"]
|
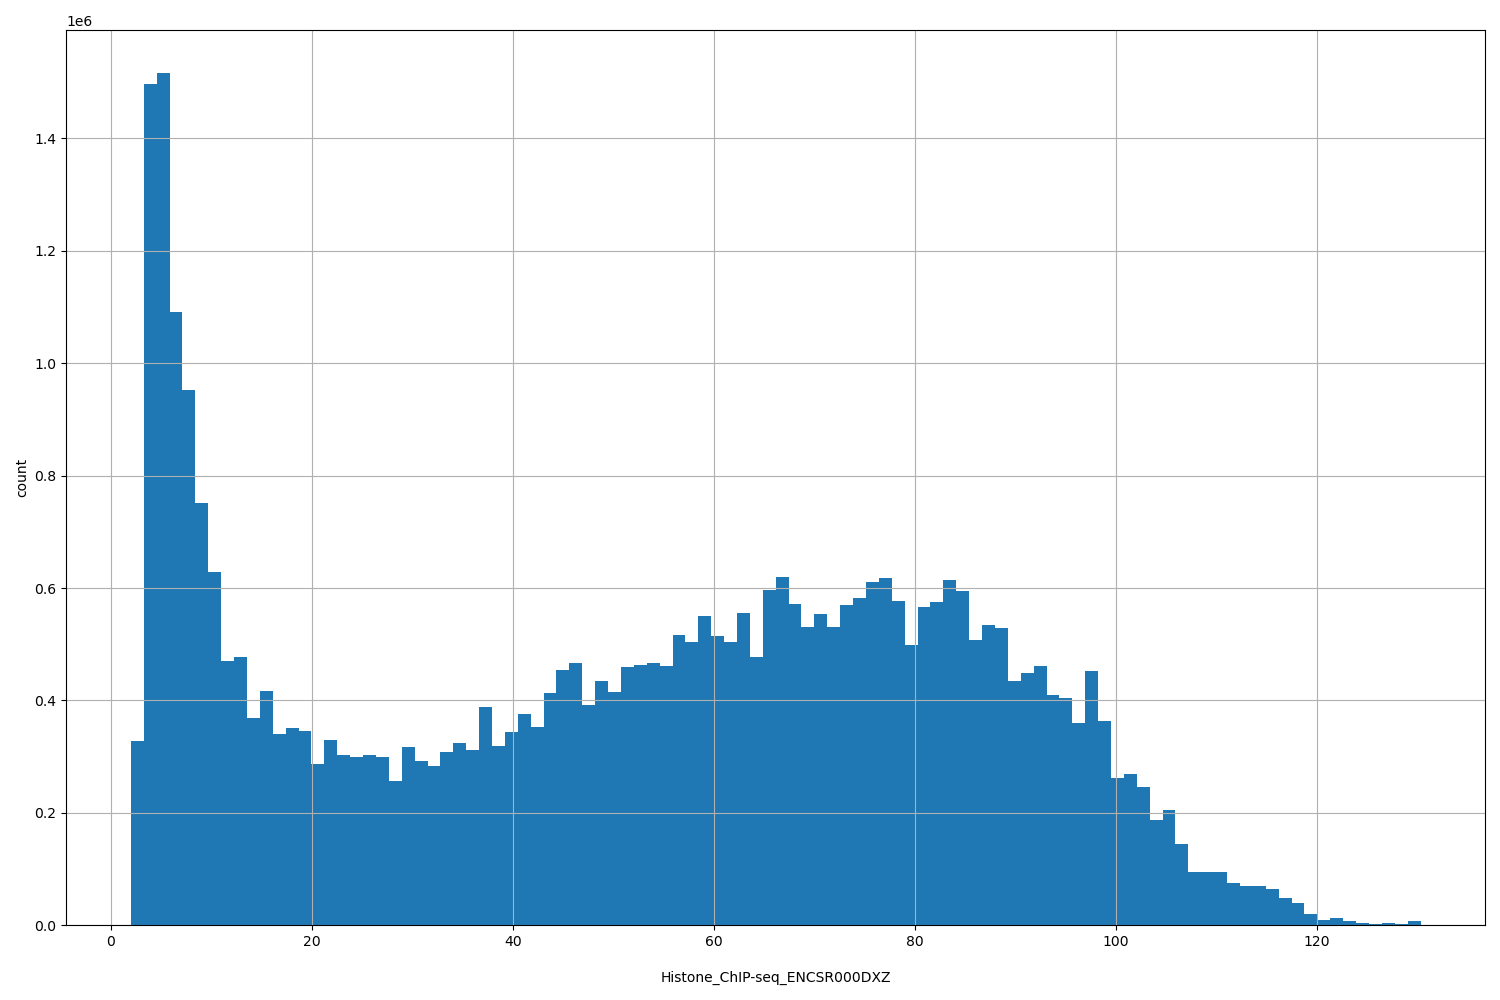 |
[2.01, 130] |
|
n counts base pairs; sd is the population standard deviation.
Coverage
| Chromosome | Covered positions | Covered % | Segments |
|---|---|---|---|
| all chromosomes | 39426855 | 1.23% | 31633 |
| chr1 | 3872704 | 1.56% | 3065 |
| chr2 | 2810003 | 1.16% | 2310 |
| chr3 | 2276434 | 1.15% | 1807 |
| chr4 | 1654756 | 0.87% | 1354 |
| chr5 | 1977944 | 1.09% | 1546 |
| chr6 | 2431748 | 1.42% | 1925 |
| chr7 | 1916029 | 1.20% | 1541 |
| chr8 | 1537296 | 1.06% | 1300 |
| chr9 | 1632016 | 1.18% | 1368 |
| chr10 | 1691300 | 1.26% | 1418 |
| chr11 | 2136736 | 1.58% | 1607 |
| chr12 | 2128619 | 1.60% | 1607 |
| chr13 | 872767 | 0.76% | 783 |
| chr14 | 1260370 | 1.18% | 982 |
| chr15 | 1313235 | 1.29% | 1024 |
| chr16 | 1506220 | 1.67% | 1217 |
| chr17 | 2218686 | 2.66% | 1702 |
| chr18 | 702254 | 0.87% | 635 |
| chr19 | 2232509 | 3.81% | 1775 |
| chr20 | 954272 | 1.48% | 781 |
| chr21 | 376204 | 0.81% | 321 |
| chr22 | 791397 | 1.56% | 662 |
| chrX | 1133356 | 0.73% | 903 |
| 3343 contigs with no values (186304500 bp) | 0 | 0.00% | 0 |
Segment lengths
| segments | min | max | mean | median | |
|---|---|---|---|---|---|
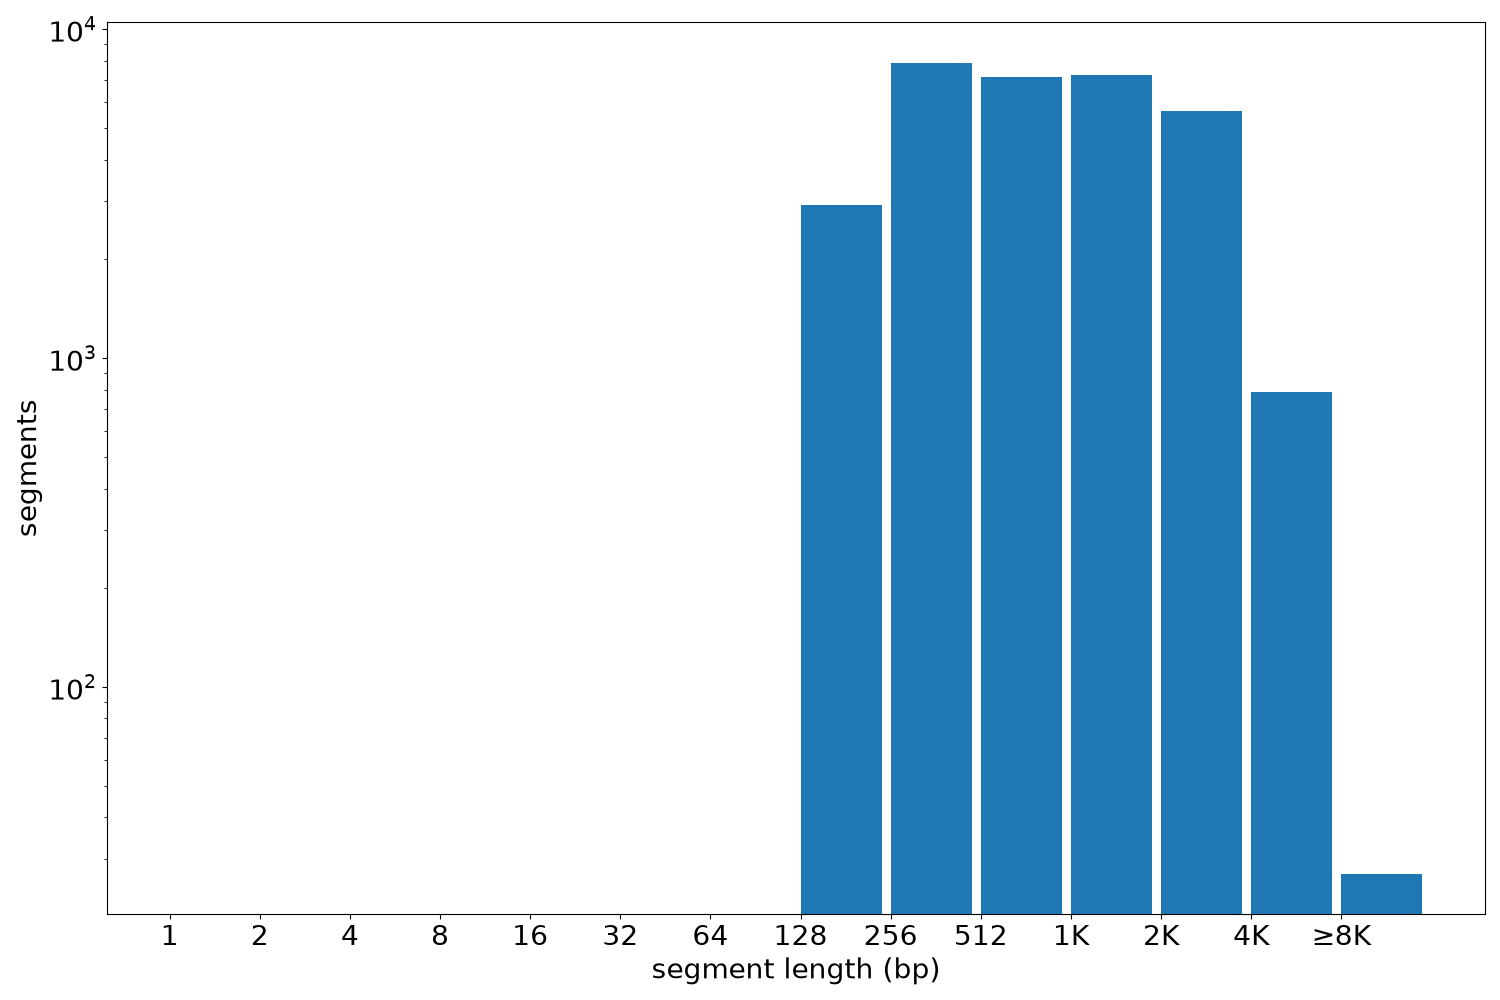
| segments | 31633 | 190 | 15621 | 1246.38 | 818 |
Files
| Filename | Size | md5 |
|---|---|---|
| ENCFF033PCY.bed.gz | 789.76 KB | 99963c3ceb38f67a8f8c225efa8cfb7a |
| ENCFF033PCY.tabix.bed.gz | 355.92 KB | f87c00c5cc830021380bdcac91273ec5 |
| ENCFF033PCY.tabix.bed.gz.tbi | 179.34 KB | 055ba4c7dad5e4f9a11ee88439d7727b |
| genomic_resource.yaml | 5.42 KB | a85718582ca81e10b0f5c382dc636d39 |
| statistics/ |