Resource
| Id | Histone_ChIP-seq/ENCSR000DPD |
|---|---|
| Type | position_score |
| Version | 0 |
| Summary | Histone_ChIP-seq ENCSR000DPD [biosample_summary="Homo sapiens A549" and target="H3K4me3"] |
| Description |
status: released biological_replicates: Rep 1, Rep 2 summary: output_type: pseudoreplicated peaks audit_internal_action: Released analysis {ENCAN362JHZ|/analyses/ENCAN362JHZ/} has in progress subobject document {5ac3c992-1924-4f04-b980-d9e72f083bc0|/documents/5ac3c992-1924-4f04-b980-d9e72f083bc0/} audit_internal_action: Released analysis {ENCAN362JHZ|/analyses/ENCAN362JHZ/} has in progress subobject quality standard {encode4-histone-chip|/quality-standards/encode4-histone-chip/} audit_warning: Processed alignments file {ENCFF651IDK|/files/ENCFF651IDK/} processed by ChIP-seq ENCODE4 v1.5.1 GRCh38 pipeline has 12766478 usable fragments. The minimum ENCODE standard for each replicate in a ChIP-seq experiment targeting H3K4me3-human and investigated as a narrow histone mark is 10 million usable fragments. The recommended value is > 20 million, but > 10 million is acceptable. (See {ENCODE ChIP-seq data standards|/data-standards/chip-seq/}) audit_warning: Processed alignments file {ENCFF252ASG|/files/ENCFF252ASG/} processed by ChIP-seq ENCODE4 v1.5.1 GRCh38 pipeline has 13591011 usable fragments. The minimum ENCODE standard for each replicate in a ChIP-seq experiment targeting H3K4me3-human and investigated as a narrow histone mark is 10 million usable fragments. The recommended value is > 20 million, but > 10 million is acceptable. (See {ENCODE ChIP-seq data standards|/data-standards/chip-seq/}) audit_warning: PBC1 (PCR Bottlenecking Coefficient 1, M1/M_distinct) is the ratio of the number of genomic locations where exactly one read maps uniquely (M1) to the number of genomic locations where some reads map (M_distinct). A PBC1 value in the range 0 - 0.5 is severe bottlenecking, 0.5 - 0.8 is moderate bottlenecking, 0.8 - 0.9 is mild bottlenecking, and > 0.9 is no bottlenecking. PBC1 value > 0.9 is recommended, but > 0.8 is acceptable. ENCODE processed alignments file {ENCFF651IDK|/files/ENCFF651IDK/} processed by ChIP-seq ENCODE4 v1.5.1 GRCh38 pipeline was generated from a library with PBC1 value of 0.86. audit_warning: PBC2 (PCR Bottlenecking Coefficient 2, M1/M2) is the ratio of the number of genomic locations where exactly one read maps uniquely (M1) to the number of genomic locations where two reads map uniquely (M2). A PBC2 value in the range 0 - 1 is severe bottlenecking, 1 - 3 is moderate bottlenecking, 3 - 10 is mild bottlenecking, > 10 is no bottlenecking. PBC2 value > 10 is recommended, but > 3 is acceptable. ENCODE processed alignments file {ENCFF651IDK|/files/ENCFF651IDK/} processed by ChIP-seq ENCODE4 v1.5.1 GRCh38 pipeline was generated from a library with PBC2 value of 7.55. audit_warning: PBC1 (PCR Bottlenecking Coefficient 1, M1/M_distinct) is the ratio of the number of genomic locations where exactly one read maps uniquely (M1) to the number of genomic locations where some reads map (M_distinct). A PBC1 value in the range 0 - 0.5 is severe bottlenecking, 0.5 - 0.8 is moderate bottlenecking, 0.8 - 0.9 is mild bottlenecking, and > 0.9 is no bottlenecking. PBC1 value > 0.9 is recommended, but > 0.8 is acceptable. ENCODE processed alignments file {ENCFF252ASG|/files/ENCFF252ASG/} processed by ChIP-seq ENCODE4 v1.5.1 GRCh38 pipeline was generated from a library with PBC1 value of 0.86. audit_warning: PBC2 (PCR Bottlenecking Coefficient 2, M1/M2) is the ratio of the number of genomic locations where exactly one read maps uniquely (M1) to the number of genomic locations where two reads map uniquely (M2). A PBC2 value in the range 0 - 1 is severe bottlenecking, 1 - 3 is moderate bottlenecking, 3 - 10 is mild bottlenecking, > 10 is no bottlenecking. PBC2 value > 10 is recommended, but > 3 is acceptable. ENCODE processed alignments file {ENCFF252ASG|/files/ENCFF252ASG/} processed by ChIP-seq ENCODE4 v1.5.1 GRCh38 pipeline was generated from a library with PBC2 value of 7.34. |
| Labels |
|
Scores (1)
| ID | Type | Default annotation | Description | Histogram | Range | Summary |
|---|---|---|---|---|---|---|
| Histone_ChIP-seq_ENCSR000DPD | float |
Histone_ChIP-seq_ENCSR000DPD |
Histone_ChIP-seq ENCSR000DPD [biosample_summary="Homo sapiens A549" and target="H3K4me3"]
|
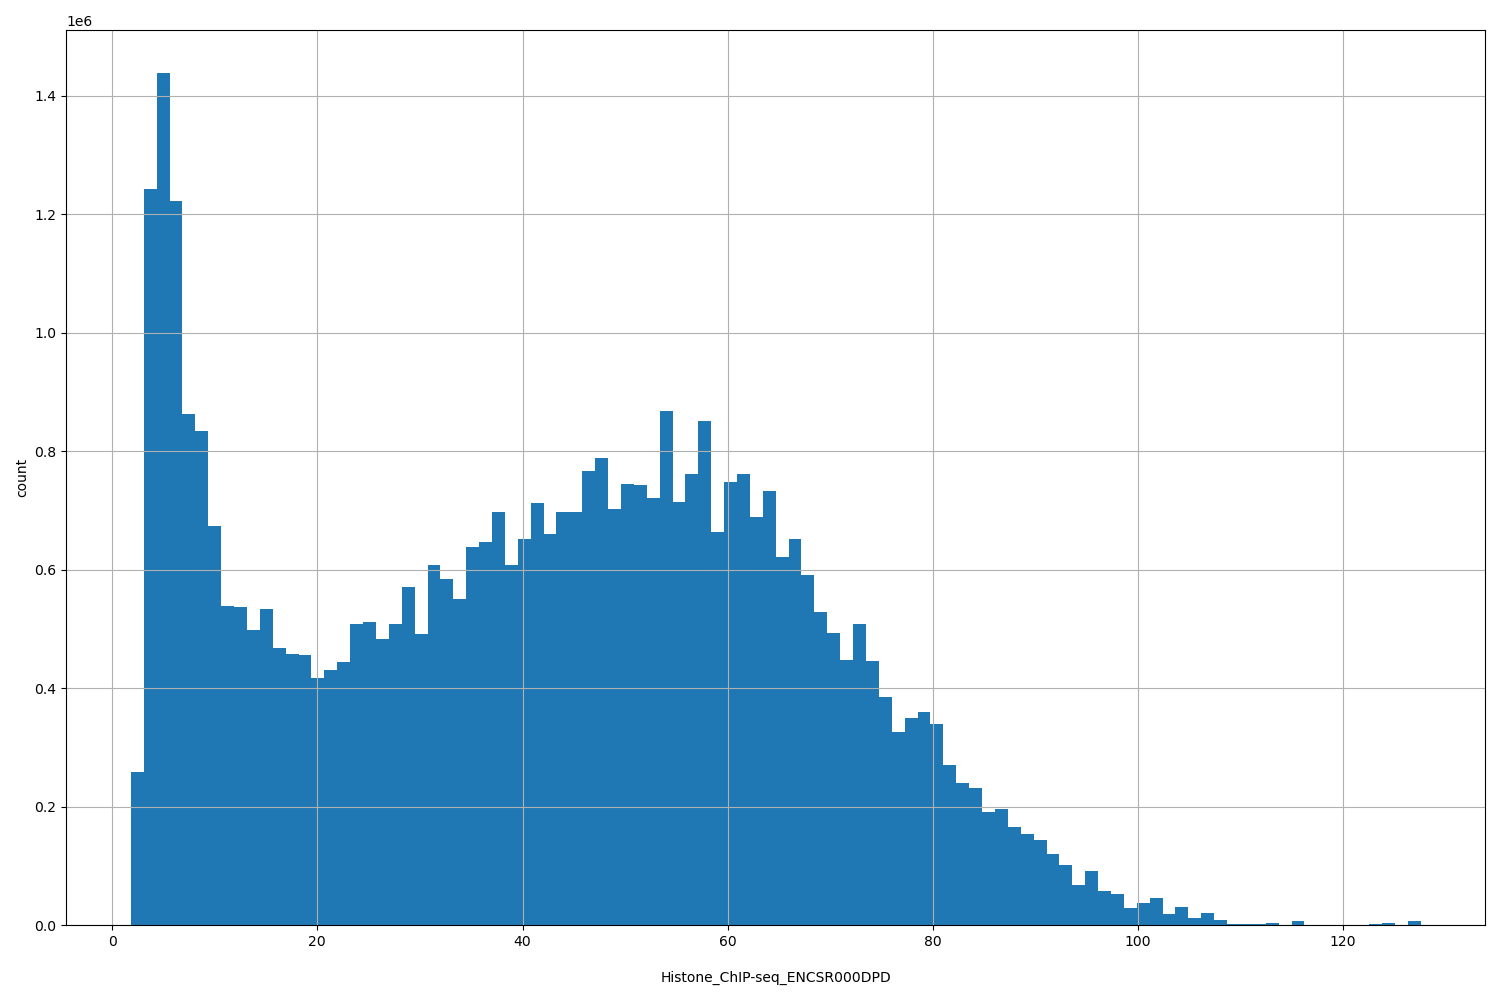 |
[1.82, 128] |
|
n counts base pairs; sd is the population standard deviation.
Coverage
| Chromosome | Covered positions | Covered % | Segments |
|---|---|---|---|
| all chromosomes | 41775242 | 1.30% | 32532 |
| chr1 | 3928414 | 1.58% | 3050 |
| chr2 | 2987535 | 1.23% | 2324 |
| chr3 | 2319299 | 1.17% | 1778 |
| chr4 | 1693337 | 0.89% | 1356 |
| chr5 | 2024594 | 1.12% | 1523 |
| chr6 | 2491593 | 1.46% | 1861 |
| chr7 | 2038875 | 1.28% | 1667 |
| chr8 | 1611634 | 1.11% | 1286 |
| chr9 | 1804045 | 1.30% | 1448 |
| chr10 | 1906026 | 1.42% | 1522 |
| chr11 | 2146545 | 1.59% | 1593 |
| chr12 | 2324003 | 1.74% | 1682 |
| chr13 | 835985 | 0.73% | 704 |
| chr14 | 1356483 | 1.27% | 994 |
| chr15 | 1426362 | 1.40% | 1105 |
| chr16 | 1611321 | 1.78% | 1307 |
| chr17 | 2450984 | 2.94% | 1802 |
| chr18 | 696980 | 0.87% | 588 |
| chr19 | 2359446 | 4.03% | 1953 |
| chr20 | 1168051 | 1.81% | 898 |
| chr21 | 386609 | 0.83% | 316 |
| chr22 | 837443 | 1.65% | 696 |
| chrX | 1316268 | 0.84% | 1045 |
| chrY | 53410 | 0.09% | 34 |
| 3342 contigs with no values (129077085 bp) | 0 | 0.00% | 0 |
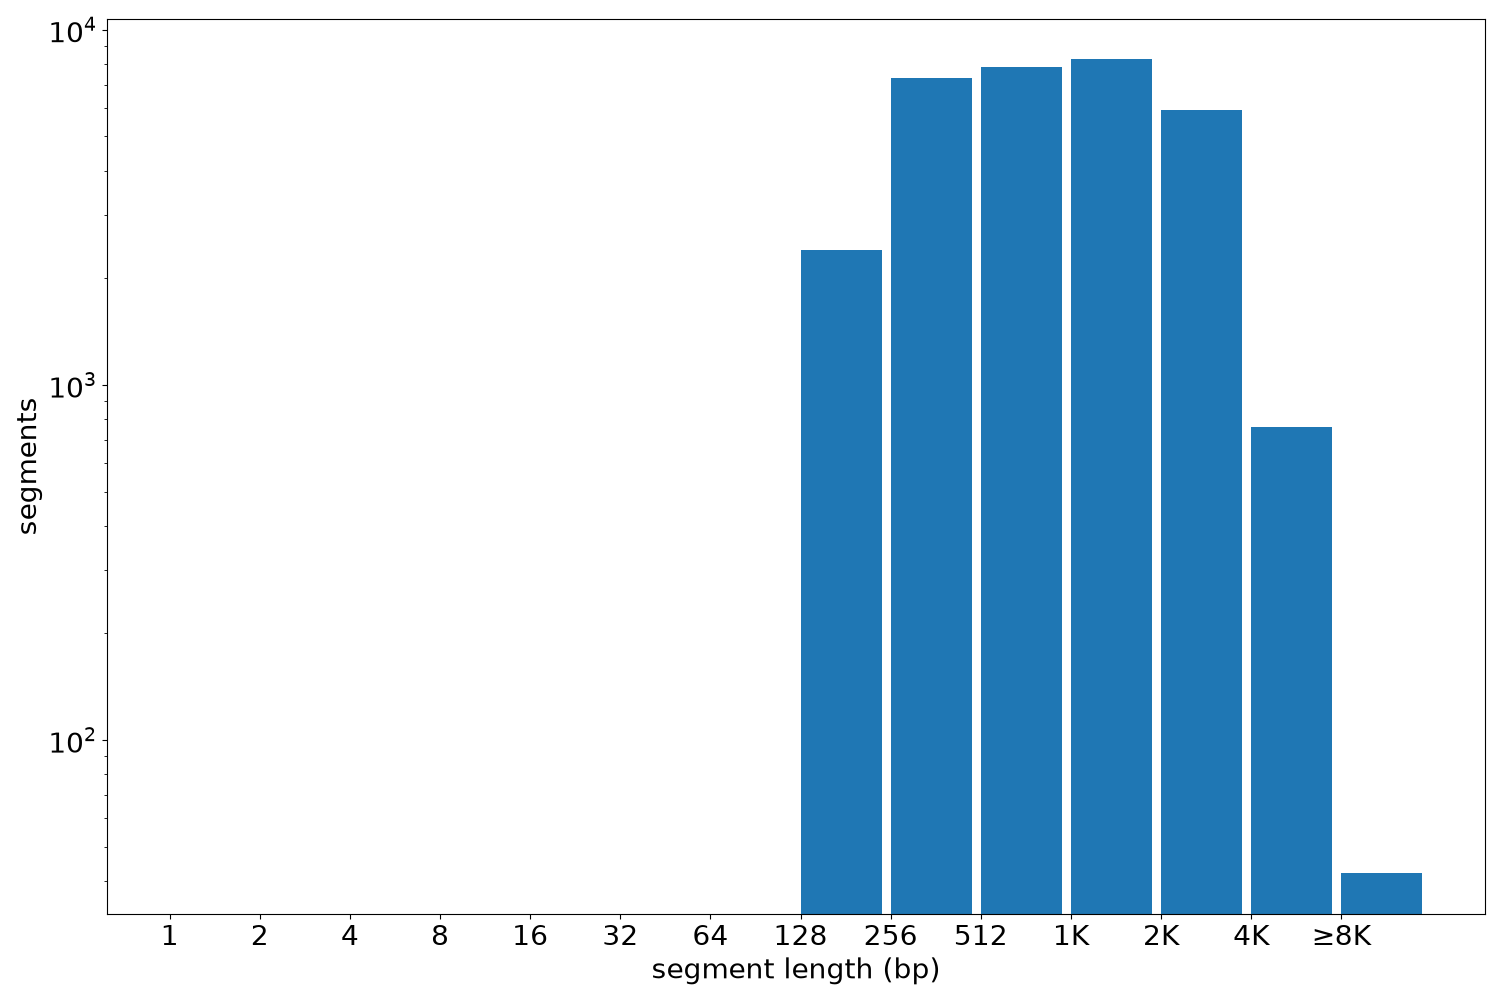
Segment lengths
| segments | min | max | mean | median | |
|---|---|---|---|---|---|
| segments | 32532 | 185 | 22126 | 1284.13 | 913 |
Files
| Filename | Size | md5 |
|---|---|---|
| ENCFF361TGO.bed.gz | 840.95 KB | 5aefcf5462cb71779018a01f6f469271 |
| ENCFF361TGO.tabix.bed.gz | 370.33 KB | b8b09baf369f9124164caed29aafe8ee |
| ENCFF361TGO.tabix.bed.gz.tbi | 178.3 KB | 74508423a62b9d7894ddf41f3b7c152b |
| genomic_resource.yaml | 5.22 KB | 837e0d9510c65c020375a2856b46c9de |
| statistics/ |