Resource
| Id | Histone_ChIP-seq/ENCSR000ARU |
|---|---|
| Type | position_score |
| Version | 0 |
| Summary | Histone_ChIP-seq ENCSR000ARU [biosample_summary="Homo sapiens astrocyte" and target="H4K20me1"] |
| Description |
status: released biological_replicates: Rep 1, Rep 2 summary: output_type: pseudoreplicated peaks audit_internal_action: Released analysis {ENCAN668BWV|/analyses/ENCAN668BWV/} has in progress subobject quality standard {encode4-histone-chip|/quality-standards/encode4-histone-chip/} audit_internal_action: Released analysis {ENCAN668BWV|/analyses/ENCAN668BWV/} has in progress subobject document {9138787b-86d7-4a78-85b4-3f9e5e425fa0|/documents/9138787b-86d7-4a78-85b4-3f9e5e425fa0/} audit_not_compliant: Processed alignments file {ENCFF683HXA|/files/ENCFF683HXA/} processed by ChIP-seq ENCODE4 v1.6.0 GRCh38 pipeline has 26400215 usable fragments. The minimum ENCODE standard for each replicate in a ChIP-seq experiment targeting H4K20me1-human and investigated as a broad histone mark is 20 million usable fragments. The recommended value is > 45 million, but > 35 million is acceptable. (See {ENCODE ChIP-seq data standards|/data-standards/chip-seq/}) |
| Labels |
|
Scores (1)
| ID | Type | Default annotation | Description | Histogram | Range | Summary |
|---|---|---|---|---|---|---|
| Histone_ChIP-seq_ENCSR000ARU | float |
Histone_ChIP-seq_ENCSR000ARU |
Histone_ChIP-seq ENCSR000ARU [biosample_summary="Homo sapiens astrocyte" and target="H4K20me1"]
|
 |
[1.61, 23.7] |
|
n counts base pairs; sd is the population standard deviation.
Coverage
| Chromosome | Covered positions | Covered % | Segments |
|---|---|---|---|
| all chromosomes | 121503819 | 3.78% | 115376 |
| chr1 | 11602103 | 4.66% | 10856 |
| chr2 | 8818078 | 3.64% | 8582 |
| chr3 | 7792112 | 3.93% | 7670 |
| chr4 | 4284862 | 2.25% | 4652 |
| chr5 | 6287643 | 3.46% | 5943 |
| chr6 | 5168832 | 3.03% | 5137 |
| chr7 | 6824260 | 4.28% | 6456 |
| chr8 | 4512578 | 3.11% | 4393 |
| chr9 | 5542970 | 4.01% | 5008 |
| chr10 | 6743899 | 5.04% | 6499 |
| chr11 | 6187941 | 4.58% | 5817 |
| chr12 | 6001549 | 4.50% | 5839 |
| chr13 | 2662518 | 2.33% | 2805 |
| chr14 | 4364059 | 4.08% | 4241 |
| chr15 | 4501663 | 4.41% | 4495 |
| chr16 | 5917426 | 6.55% | 5106 |
| chr17 | 6954112 | 8.35% | 6238 |
| chr18 | 2001470 | 2.49% | 2109 |
| chr19 | 5175038 | 8.83% | 4308 |
| chr20 | 3637807 | 5.64% | 3104 |
| chr21 | 1349768 | 2.89% | 1269 |
| chr22 | 3765848 | 7.41% | 3267 |
| chrX | 1303803 | 0.84% | 1468 |
| chrY | 103480 | 0.18% | 114 |
| 3342 contigs with no values (129077085 bp) | 0 | 0.00% | 0 |
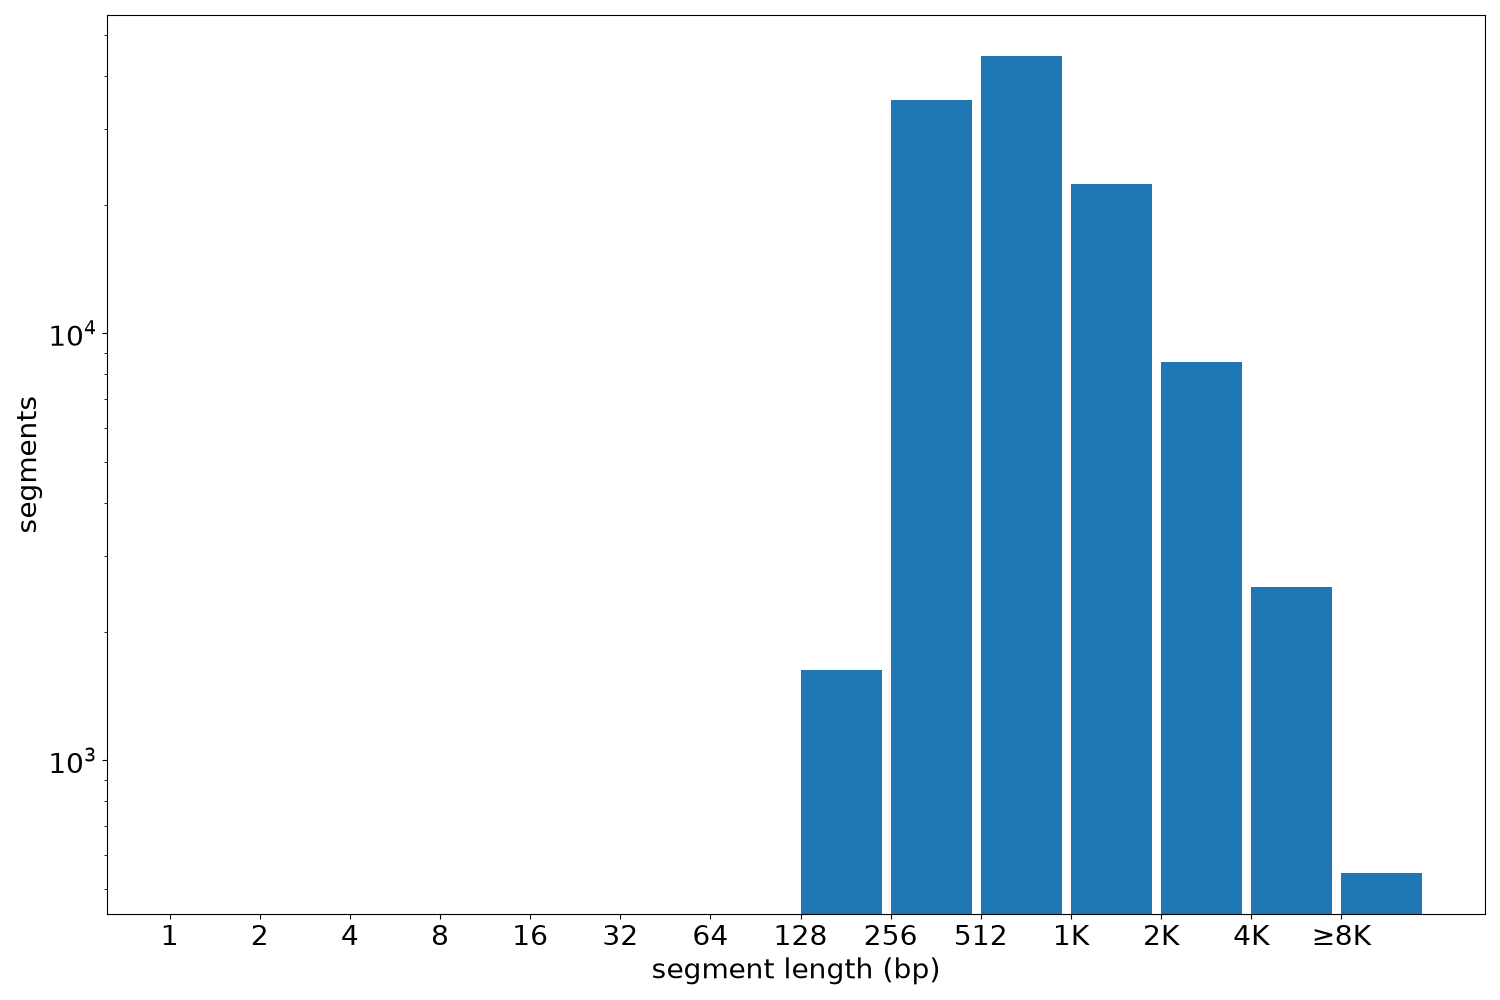
Segment lengths
| segments | min | max | mean | median | |
|---|---|---|---|---|---|
| segments | 115376 | 195 | 25836 | 1053.11 | 684 |
Files
| Filename | Size | md5 |
|---|---|---|
| ENCFF201FZW.bed.gz | 2.68 MB | 98113f5ac90b6057f247ae10f65d844b |
| ENCFF201FZW.tabix.bed.gz | 1.18 MB | beedf8506bff8ab9882e8a0290efdf78 |
| ENCFF201FZW.tabix.bed.gz.tbi | 154.64 KB | db4af79a189ccb6f52701135733fe09c |
| genomic_resource.yaml | 2.36 KB | 7f9780c606a9babf3f3351a6a42bbf63 |
| statistics/ |