Resource
| Id | DNase-seq/ENCSR828FVZ |
|---|---|
| Type | position_score |
| Version | 0 |
| Summary | DNase-seq ENCSR828FVZ [biosample_summary="Homo sapiens body of pancreas tissue female adult (53 years)"] |
| Description |
status: released biological_replicates: Rep 1 summary: female adult (53 years) output_type: peaks audit_internal_action: Archived analysis {ENCAN911LZE|/analyses/ENCAN911LZE/} has in progress subobject quality standard {encode3-dnase|/quality-standards/encode3-dnase/} audit_warning: Alignment file {ENCFF984FKS|/files/ENCFF984FKS/} processed by DNase-seq ENCODE3 GRCh38 pipeline ( {ENCPL202DNS|/pipelines/ENCPL202DNS/} ) for GRCh38 assembly has 42828714 mapped reads. According to ENCODE standards, conventional DNase-seq profile requires a minimum of 20 million uniquely mapped reads to generate a reliable SPOT (Signal Portion of Tags) score. The recommended value is > 50 million. For deep, foot-printing depth DNase-seq 150-200 million uniquely mapped reads are recommended. (See {ENCODE DNase-seq data standards|/data-standards/dnase-seq/}) |
| Labels |
|
Scores (1)
| ID | Type | Default annotation | Description | Histogram | Range | Summary |
|---|---|---|---|---|---|---|
| DNase-seq_ENCSR828FVZ | float |
DNase-seq_ENCSR828FVZ |
DNase-seq ENCSR828FVZ [biosample_summary="Homo sapiens body of pancreas tissue female adult (53 years)"]
|
 |
[7, 2.46e+04] |
|
n counts base pairs; sd is the population standard deviation.
Coverage
| Chromosome | Covered positions | Covered % | Segments |
|---|---|---|---|
| all chromosomes | 11651692 | 0.36% | 77607 |
| chr1 | 1183288 | 0.48% | 7884 |
| chr2 | 876818 | 0.36% | 5840 |
| chr3 | 712095 | 0.36% | 4742 |
| chr4 | 475943 | 0.25% | 3168 |
| chr5 | 559336 | 0.31% | 3727 |
| chr6 | 643196 | 0.38% | 4284 |
| chr7 | 578890 | 0.36% | 3854 |
| chr8 | 487458 | 0.34% | 3249 |
| chr9 | 511287 | 0.37% | 3405 |
| chr10 | 561704 | 0.42% | 3740 |
| chr11 | 636234 | 0.47% | 4234 |
| chr12 | 560011 | 0.42% | 3731 |
| chr13 | 250765 | 0.22% | 1670 |
| chr14 | 395810 | 0.37% | 2638 |
| chr15 | 402433 | 0.39% | 2678 |
| chr16 | 442358 | 0.49% | 2945 |
| chr17 | 588393 | 0.71% | 3921 |
| chr18 | 219822 | 0.27% | 1466 |
| chr19 | 531473 | 0.91% | 3539 |
| chr20 | 325670 | 0.51% | 2169 |
| chr21 | 130500 | 0.28% | 870 |
| chr22 | 265560 | 0.52% | 1769 |
| chrX | 311898 | 0.20% | 2079 |
| chrY | 750 | <0.01% | 5 |
| 3342 contigs with no values (129077085 bp) | 0 | 0.00% | 0 |
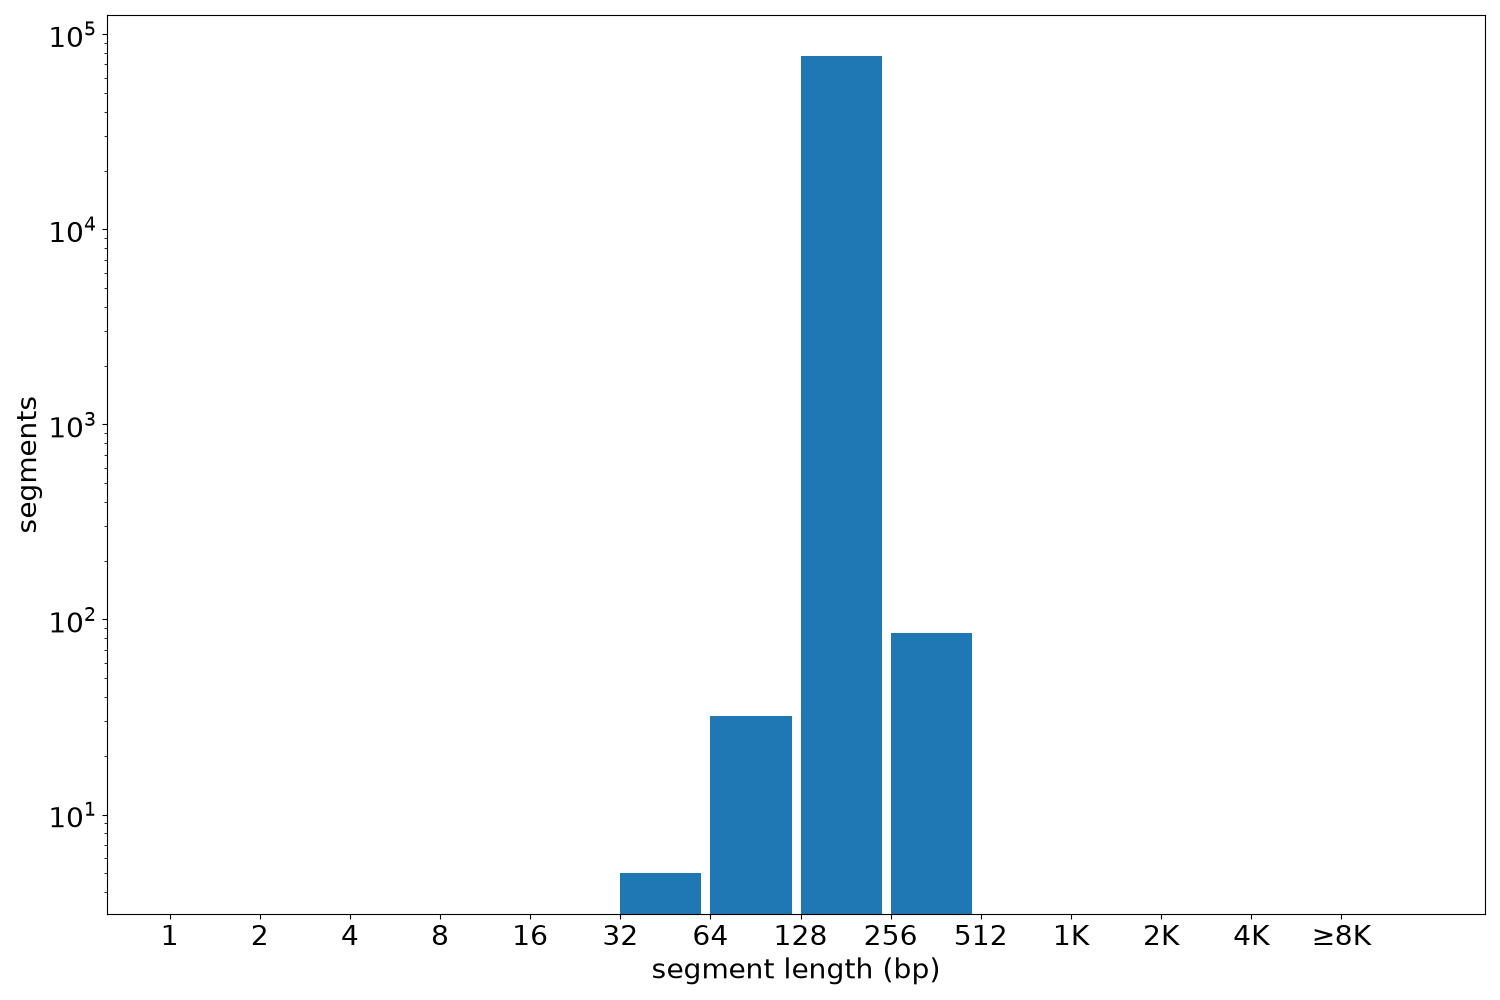
Segment lengths
| segments | min | max | mean | median | |
|---|---|---|---|---|---|
| segments | 77607 | 38 | 450 | 150.14 | 150 |
Files
| Filename | Size | md5 |
|---|---|---|
| ENCFF894HSB.bed.gz | 771.49 KB | eaf8a3aac027a9b3dc55f7929ca61854 |
| ENCFF894HSB.tabix.bed.gz | 664.7 KB | 39739cce6348a765639b14b4ca405177 |
| ENCFF894HSB.tabix.bed.gz.tbi | 357.66 KB | 49b14b187a7161d42dad140561239801 |
| genomic_resource.yaml | 2.01 KB | 9daf38b5d6a58d0667bb3dd5e101d1f5 |
| statistics/ |