Resource
| Id | DNase-seq/ENCSR419MZH |
|---|---|
| Type | position_score |
| Version | 0 |
| Summary | DNase-seq ENCSR419MZH [biosample_summary="Homo sapiens adrenal gland tissue female embryo (108 days)"] |
| Description |
status: released biological_replicates: Rep 1 summary: female embryo (108 days) output_type: peaks audit_warning: Alignment file {ENCFF729HDS|/files/ENCFF729HDS/} processed by DNase-seq ENCODE4 v3.0.0-alpha.2 GRCh38 pipeline ( {ENCPL848KLD|/pipelines/ENCPL848KLD/} ) for GRCh38 assembly has 27129463 mapped reads. According to ENCODE standards, conventional DNase-seq profile requires a minimum of 20 million uniquely mapped reads to generate a reliable SPOT (Signal Portion of Tags) score. The recommended value is > 50 million. For deep, foot-printing depth DNase-seq 150-200 million uniquely mapped reads are recommended. (See {ENCODE DNase-seq data standards|/data-standards/dnase-seq-encode4/}) audit_warning: Signal Portion of Tags (SPOT) is a measure of enrichment, analogous to the commonly used fraction of reads in peaks metric. ENCODE processed alignment files {ENCFF729HDS|/files/ENCFF729HDS/} processed by DNase-seq ENCODE4 v3.0.0-alpha.2 GRCh38 pipeline ({ENCPL848KLD|/pipelines/ENCPL848KLD/}) for GRCh38 assembly have a SPOT1 score of 0.30. According to ENCODE standards, SPOT1 score of 0.4 or higher is considered a product of high quality data. Any sample with a SPOT1 score <0.3 should be targeted for replacement with a higher quality sample, and a SPOT1 score of 0.25 is considered minimally acceptable SPOT1 score of 0.25 is considered minimally acceptable for rare and hard to find primary tissues. (See {ENCODE DNase-seq data standards|/data-standards/dnase-seq-encode4/}) |
| Labels |
|
Scores (1)
| ID | Type | Default annotation | Description | Histogram | Range | Summary |
|---|---|---|---|---|---|---|
| DNase-seq_ENCSR419MZH | float |
DNase-seq_ENCSR419MZH |
DNase-seq ENCSR419MZH [biosample_summary="Homo sapiens adrenal gland tissue female embryo (108 days)"]
|
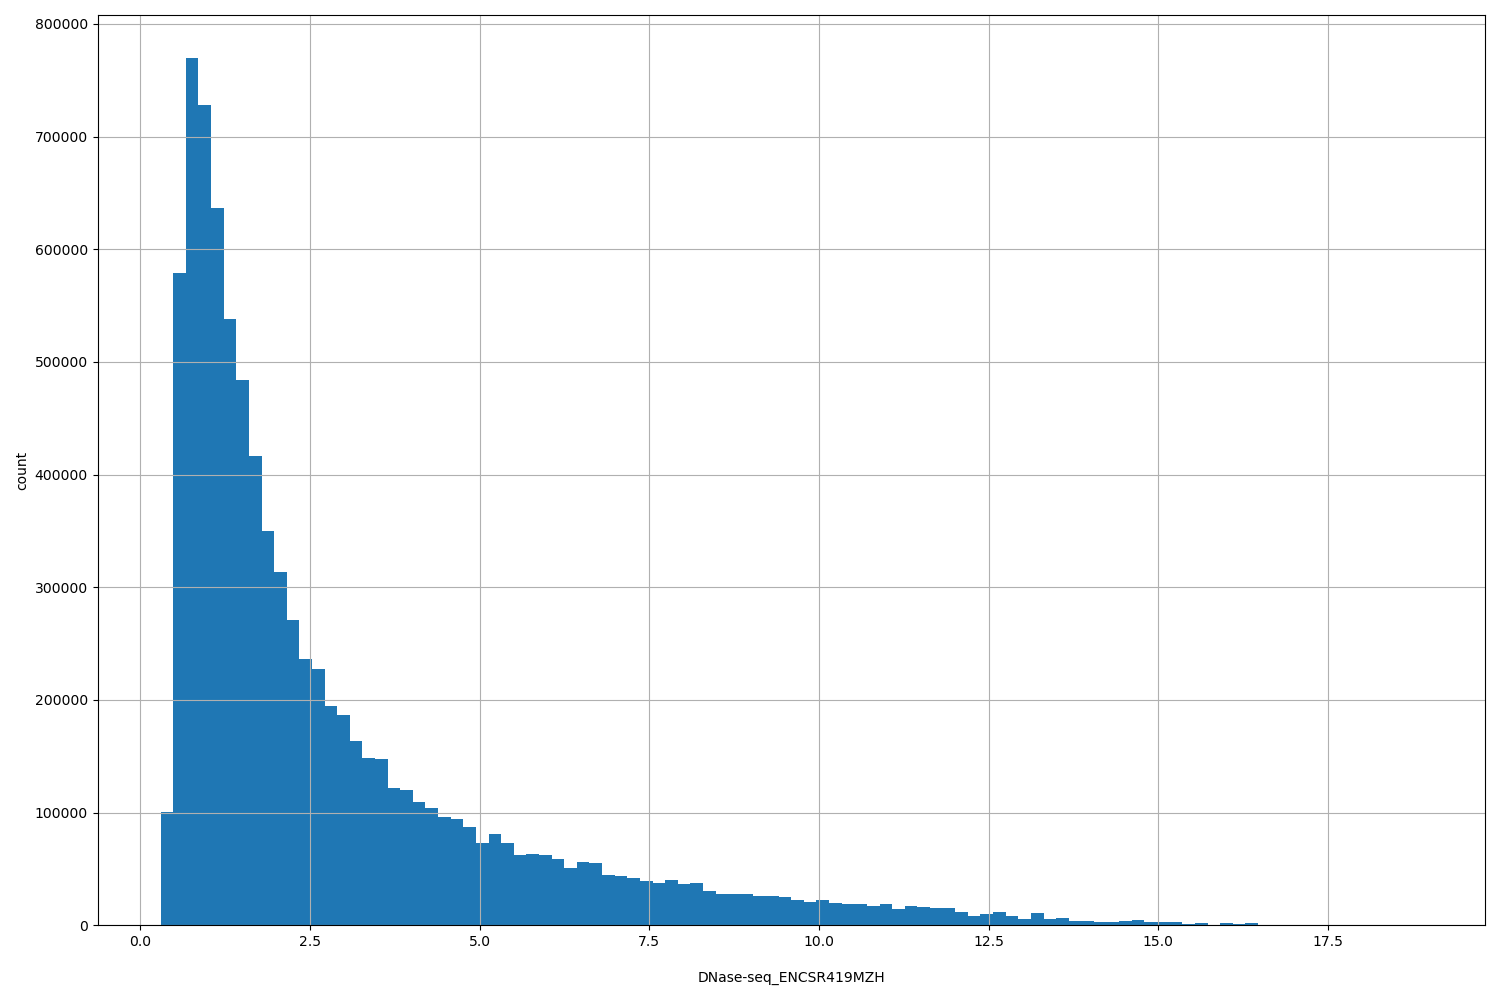 |
[0.296, 18.9] |
|
n counts base pairs; sd is the population standard deviation.
Coverage
| Chromosome | Covered positions | Covered % | Segments |
|---|---|---|---|
| all chromosomes | 8741033 | 0.27% | 50480 |
| chr1 | 808911 | 0.32% | 4659 |
| chr2 | 678125 | 0.28% | 3937 |
| chr3 | 562362 | 0.28% | 3294 |
| chr4 | 406188 | 0.21% | 2366 |
| chr5 | 456054 | 0.25% | 2668 |
| chr6 | 498574 | 0.29% | 2905 |
| chr7 | 448142 | 0.28% | 2605 |
| chr8 | 381421 | 0.26% | 2235 |
| chr9 | 362970 | 0.26% | 2115 |
| chr10 | 414917 | 0.31% | 2414 |
| chr11 | 457054 | 0.34% | 2637 |
| chr12 | 433411 | 0.33% | 2515 |
| chr13 | 238657 | 0.21% | 1376 |
| chr14 | 281100 | 0.26% | 1641 |
| chr15 | 278605 | 0.27% | 1617 |
| chr16 | 293864 | 0.33% | 1683 |
| chr17 | 380899 | 0.46% | 2161 |
| chr18 | 180696 | 0.22% | 1089 |
| chr19 | 429162 | 0.73% | 2258 |
| chr20 | 234589 | 0.36% | 1355 |
| chr21 | 100635 | 0.22% | 592 |
| chr22 | 171218 | 0.34% | 967 |
| chrX | 243238 | 0.16% | 1389 |
| chrY | 241 | <0.01% | 2 |
| 3342 contigs with no values (129077085 bp) | 0 | 0.00% | 0 |
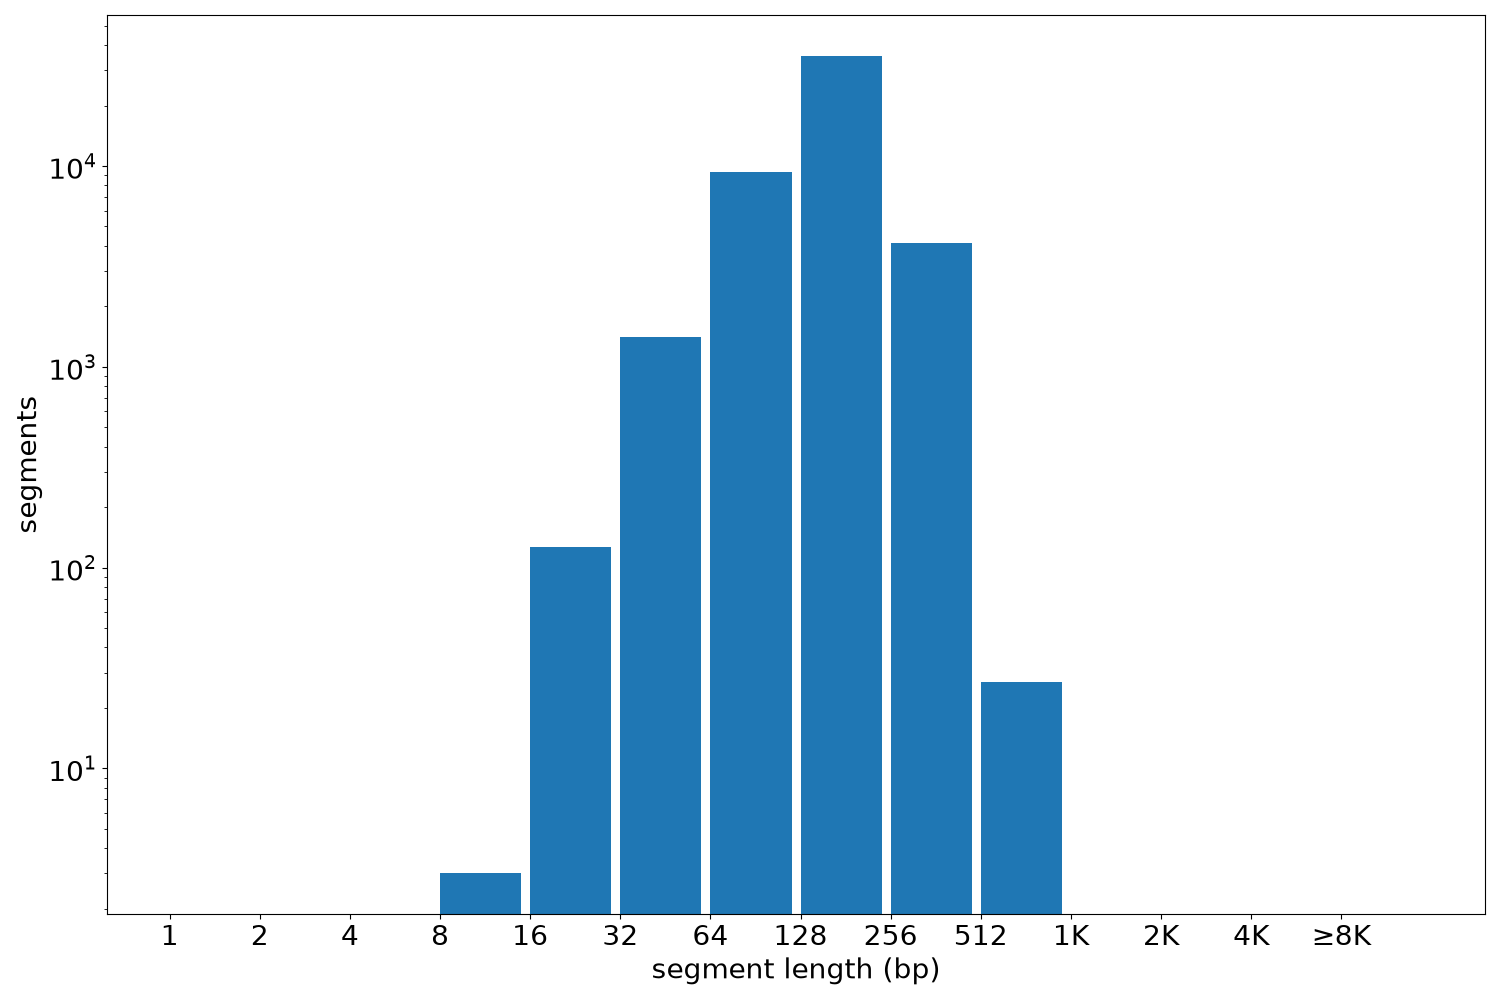
Segment lengths
| segments | min | max | mean | median | |
|---|---|---|---|---|---|
| segments | 50480 | 9 | 740 | 173.16 | 179 |
Files
| Filename | Size | md5 |
|---|---|---|
| ENCFF101DAL.bed.gz | 532.98 KB | c257bfeee63e1ab26d7e4172b6a88eec |
| ENCFF101DAL.tabix.bed.gz | 474.14 KB | e8680bccfea5291ff619362dfb2a5359 |
| ENCFF101DAL.tabix.bed.gz.tbi | 296.53 KB | 65770cda83fc32068185b1004029d586 |
| genomic_resource.yaml | 2.67 KB | aef85ac818cb911c97e2d4d2d05513ef |
| statistics/ |