Resource
| Id | DNase-seq/ENCSR188JLO |
|---|---|
| Type | position_score |
| Version | 0 |
| Summary | DNase-seq ENCSR188JLO [biosample_summary="Homo sapiens small intestine tissue male embryo (105 days)"] |
| Description |
status: released biological_replicates: Rep 1 summary: male embryo (105 days) output_type: peaks audit_error: Signal Portion of Tags (SPOT) is a measure of enrichment, analogous to the commonly used fraction of reads in peaks metric. ENCODE processed alignment files {ENCFF395WTZ|/files/ENCFF395WTZ/} processed by DNase-seq ENCODE4 v3.0.0-alpha.2 GRCh38 pipeline ({ENCPL848KLD|/pipelines/ENCPL848KLD/}) for GRCh38 assembly have a SPOT1 score of 0.24. According to ENCODE standards, SPOT1 score of 0.4 or higher is considered a product of high quality data. Any sample with a SPOT1 score <0.3 should be targeted for replacement with a higher quality sample, and a SPOT1 score of 0.25 is considered minimally acceptable SPOT1 score of 0.25 is considered minimally acceptable for rare and hard to find primary tissues. (See {ENCODE DNase-seq data standards|/data-standards/dnase-seq-encode4/}) audit_warning: Alignment file {ENCFF395WTZ|/files/ENCFF395WTZ/} processed by DNase-seq ENCODE4 v3.0.0-alpha.2 GRCh38 pipeline ( {ENCPL848KLD|/pipelines/ENCPL848KLD/} ) for GRCh38 assembly has 39925715 mapped reads. According to ENCODE standards, conventional DNase-seq profile requires a minimum of 20 million uniquely mapped reads to generate a reliable SPOT (Signal Portion of Tags) score. The recommended value is > 50 million. For deep, foot-printing depth DNase-seq 150-200 million uniquely mapped reads are recommended. (See {ENCODE DNase-seq data standards|/data-standards/dnase-seq-encode4/}) |
| Labels |
|
Scores (1)
| ID | Type | Default annotation | Description | Histogram | Range | Summary |
|---|---|---|---|---|---|---|
| DNase-seq_ENCSR188JLO | float |
DNase-seq_ENCSR188JLO |
DNase-seq ENCSR188JLO [biosample_summary="Homo sapiens small intestine tissue male embryo (105 days)"]
|
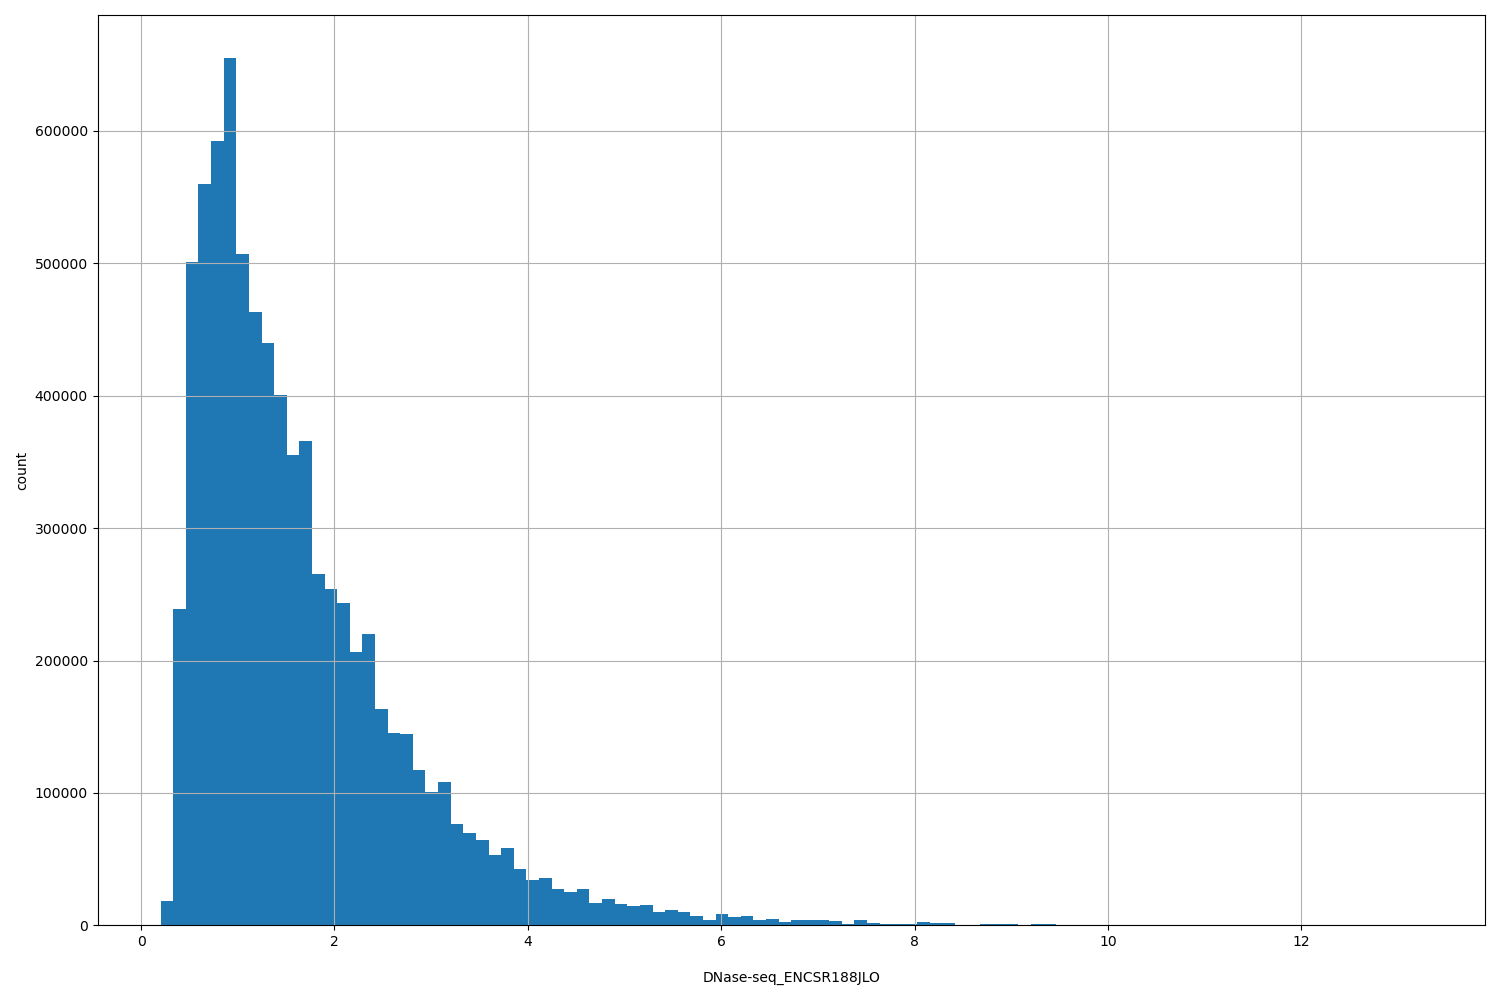 |
[0.201, 13.2] |
|
n counts base pairs; sd is the population standard deviation.
Coverage
| Chromosome | Covered positions | Covered % | Segments |
|---|---|---|---|
| all chromosomes | 7778386 | 0.24% | 40566 |
| chr1 | 743722 | 0.30% | 3860 |
| chr2 | 626726 | 0.26% | 3285 |
| chr3 | 506135 | 0.26% | 2661 |
| chr4 | 432297 | 0.23% | 2244 |
| chr5 | 427042 | 0.24% | 2233 |
| chr6 | 484660 | 0.28% | 2492 |
| chr7 | 393582 | 0.25% | 2080 |
| chr8 | 342214 | 0.24% | 1797 |
| chr9 | 317525 | 0.23% | 1675 |
| chr10 | 353837 | 0.26% | 1848 |
| chr11 | 396138 | 0.29% | 2070 |
| chr12 | 397670 | 0.30% | 2110 |
| chr13 | 212504 | 0.19% | 1080 |
| chr14 | 255106 | 0.24% | 1319 |
| chr15 | 240419 | 0.24% | 1282 |
| chr16 | 253151 | 0.28% | 1320 |
| chr17 | 305674 | 0.37% | 1586 |
| chr18 | 188389 | 0.23% | 975 |
| chr19 | 327440 | 0.56% | 1576 |
| chr20 | 181821 | 0.28% | 971 |
| chr21 | 85558 | 0.18% | 456 |
| chr22 | 126414 | 0.25% | 659 |
| chrX | 170864 | 0.11% | 938 |
| chrY | 9498 | 0.02% | 49 |
| 3342 contigs with no values (129077085 bp) | 0 | 0.00% | 0 |
Segment lengths
| segments | min | max | mean | median | |
|---|---|---|---|---|---|
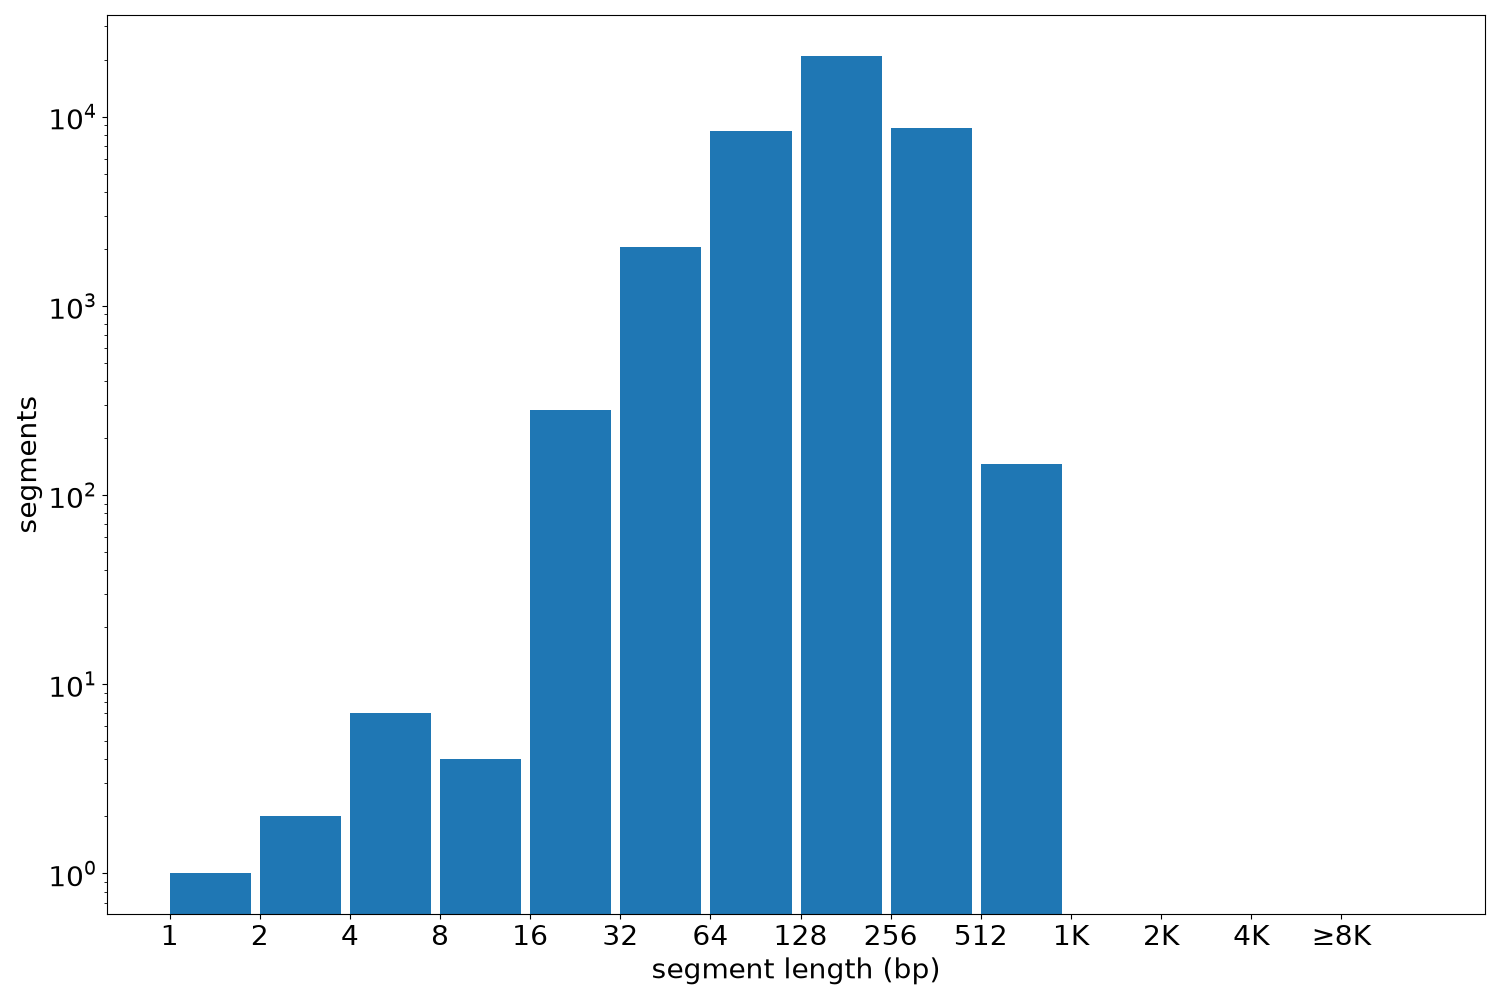
| segments | 40566 | 1 | 860 | 191.75 | 189 |
Files
| Filename | Size | md5 |
|---|---|---|
| ENCFF630RAO.bed.gz | 424.76 KB | 5da7bcc87a78d159b55c5fc96868e8c0 |
| ENCFF630RAO.tabix.bed.gz | 379.29 KB | aefb7c59b65e9e2bc4ba38b4d9020e22 |
| ENCFF630RAO.tabix.bed.gz.tbi | 238.61 KB | bd355c5fbcf2348d3813f5c0f80f1ae8 |
| genomic_resource.yaml | 2.67 KB | 24a523aa4ca5c5acb88523aab9352606 |
| statistics/ |