Resource
| Id | DNase-seq/ENCSR080PZL |
|---|---|
| Type | position_score |
| Version | 0 |
| Summary | DNase-seq ENCSR080PZL [biosample_summary="Homo sapiens adrenal gland tissue male embryo (101 days)"] |
| Description |
status: released biological_replicates: Rep 1 summary: male embryo (101 days) output_type: peaks audit_warning: Alignment file {ENCFF511DEJ|/files/ENCFF511DEJ/} processed by DNase-seq ENCODE4 v3.0.0-alpha.2 GRCh38 pipeline ( {ENCPL848KLD|/pipelines/ENCPL848KLD/} ) for GRCh38 assembly has 47301584 mapped reads. According to ENCODE standards, conventional DNase-seq profile requires a minimum of 20 million uniquely mapped reads to generate a reliable SPOT (Signal Portion of Tags) score. The recommended value is > 50 million. For deep, foot-printing depth DNase-seq 150-200 million uniquely mapped reads are recommended. (See {ENCODE DNase-seq data standards|/data-standards/dnase-seq-encode4/}) audit_warning: Signal Portion of Tags (SPOT) is a measure of enrichment, analogous to the commonly used fraction of reads in peaks metric. ENCODE processed alignment files {ENCFF511DEJ|/files/ENCFF511DEJ/} processed by DNase-seq ENCODE4 v3.0.0-alpha.2 GRCh38 pipeline ({ENCPL848KLD|/pipelines/ENCPL848KLD/}) for GRCh38 assembly have a SPOT1 score of 0.28. According to ENCODE standards, SPOT1 score of 0.4 or higher is considered a product of high quality data. Any sample with a SPOT1 score <0.3 should be targeted for replacement with a higher quality sample, and a SPOT1 score of 0.25 is considered minimally acceptable SPOT1 score of 0.25 is considered minimally acceptable for rare and hard to find primary tissues. (See {ENCODE DNase-seq data standards|/data-standards/dnase-seq-encode4/}) |
| Labels |
|
Scores (1)
| ID | Type | Default annotation | Description | Histogram | Range | Summary |
|---|---|---|---|---|---|---|
| DNase-seq_ENCSR080PZL | float |
DNase-seq_ENCSR080PZL |
DNase-seq ENCSR080PZL [biosample_summary="Homo sapiens adrenal gland tissue male embryo (101 days)"]
|
 |
[0.149, 16.6] |
|
n counts base pairs; sd is the population standard deviation.
Coverage
| Chromosome | Covered positions | Covered % | Segments |
|---|---|---|---|
| all chromosomes | 12138196 | 0.38% | 68310 |
| chr1 | 1105519 | 0.44% | 6209 |
| chr2 | 945160 | 0.39% | 5377 |
| chr3 | 798311 | 0.40% | 4513 |
| chr4 | 610672 | 0.32% | 3456 |
| chr5 | 686366 | 0.38% | 3875 |
| chr6 | 718074 | 0.42% | 4007 |
| chr7 | 626947 | 0.39% | 3553 |
| chr8 | 554649 | 0.38% | 3140 |
| chr9 | 498620 | 0.36% | 2803 |
| chr10 | 581917 | 0.43% | 3312 |
| chr11 | 628327 | 0.47% | 3547 |
| chr12 | 600085 | 0.45% | 3382 |
| chr13 | 336312 | 0.29% | 1924 |
| chr14 | 398149 | 0.37% | 2210 |
| chr15 | 395864 | 0.39% | 2238 |
| chr16 | 390676 | 0.43% | 2199 |
| chr17 | 491988 | 0.59% | 2751 |
| chr18 | 269266 | 0.34% | 1537 |
| chr19 | 510188 | 0.87% | 2651 |
| chr20 | 312005 | 0.48% | 1768 |
| chr21 | 147543 | 0.32% | 821 |
| chr22 | 211841 | 0.42% | 1187 |
| chrX | 305437 | 0.20% | 1765 |
| chrY | 14280 | 0.02% | 85 |
| 3342 contigs with no values (129077085 bp) | 0 | 0.00% | 0 |
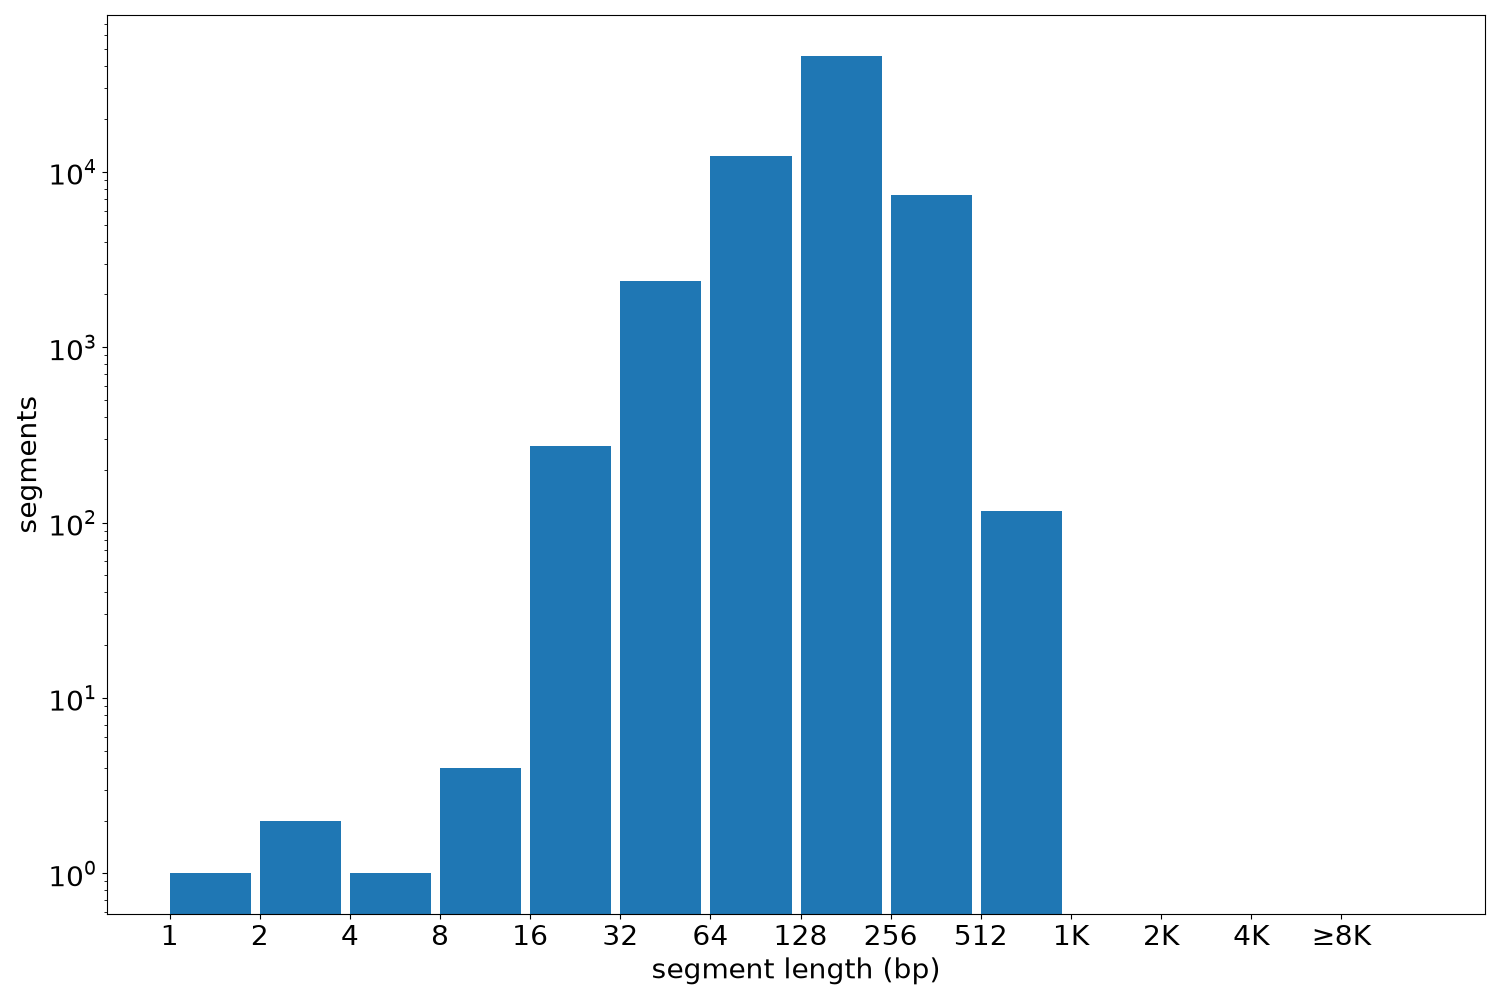
Segment lengths
| segments | min | max | mean | median | |
|---|---|---|---|---|---|
| segments | 68310 | 1 | 839 | 177.69 | 180 |
Files
| Filename | Size | md5 |
|---|---|---|
| ENCFF230LFX.bed.gz | 719.76 KB | fe5a26db06a1ca584aa8e4619a21bb05 |
| ENCFF230LFX.tabix.bed.gz | 645.9 KB | c03958ffb67132f8fddce14b47618cd7 |
| ENCFF230LFX.tabix.bed.gz.tbi | 366.94 KB | b0e5df5aeba568e9b510289e8745f35a |
| genomic_resource.yaml | 2.66 KB | 42e769b6f6eb05eef7404afa03f04a87 |
| statistics/ |