Resource
| Id | DNase-seq/ENCSR000ENB |
|---|---|
| Type | position_score |
| Version | 0 |
| Summary | DNase-seq ENCSR000ENB [biosample_summary="Homo sapiens astrocyte of the spinal cord"] |
| Description |
status: released biological_replicates: Rep 1 summary: output_type: peaks audit_internal_action: Archived analysis {ENCAN047VOT|/analyses/ENCAN047VOT/} has in progress subobject quality standard {encode3-dnase|/quality-standards/encode3-dnase/} audit_warning: Alignment file {ENCFF885IAD|/files/ENCFF885IAD/} processed by DNase-seq ENCODE3 GRCh38 pipeline ( {ENCPL001DNS|/pipelines/ENCPL001DNS/} ) for GRCh38 assembly has 37353886 mapped reads. According to ENCODE standards, conventional DNase-seq profile requires a minimum of 20 million uniquely mapped reads to generate a reliable SPOT (Signal Portion of Tags) score. The recommended value is > 50 million. For deep, foot-printing depth DNase-seq 150-200 million uniquely mapped reads are recommended. (See {ENCODE DNase-seq data standards|/data-standards/dnase-seq/}) |
| Labels |
|
Scores (1)
| ID | Type | Default annotation | Description | Histogram | Range | Summary |
|---|---|---|---|---|---|---|
| DNase-seq_ENCSR000ENB | float |
DNase-seq_ENCSR000ENB |
DNase-seq ENCSR000ENB [biosample_summary="Homo sapiens astrocyte of the spinal cord"]
|
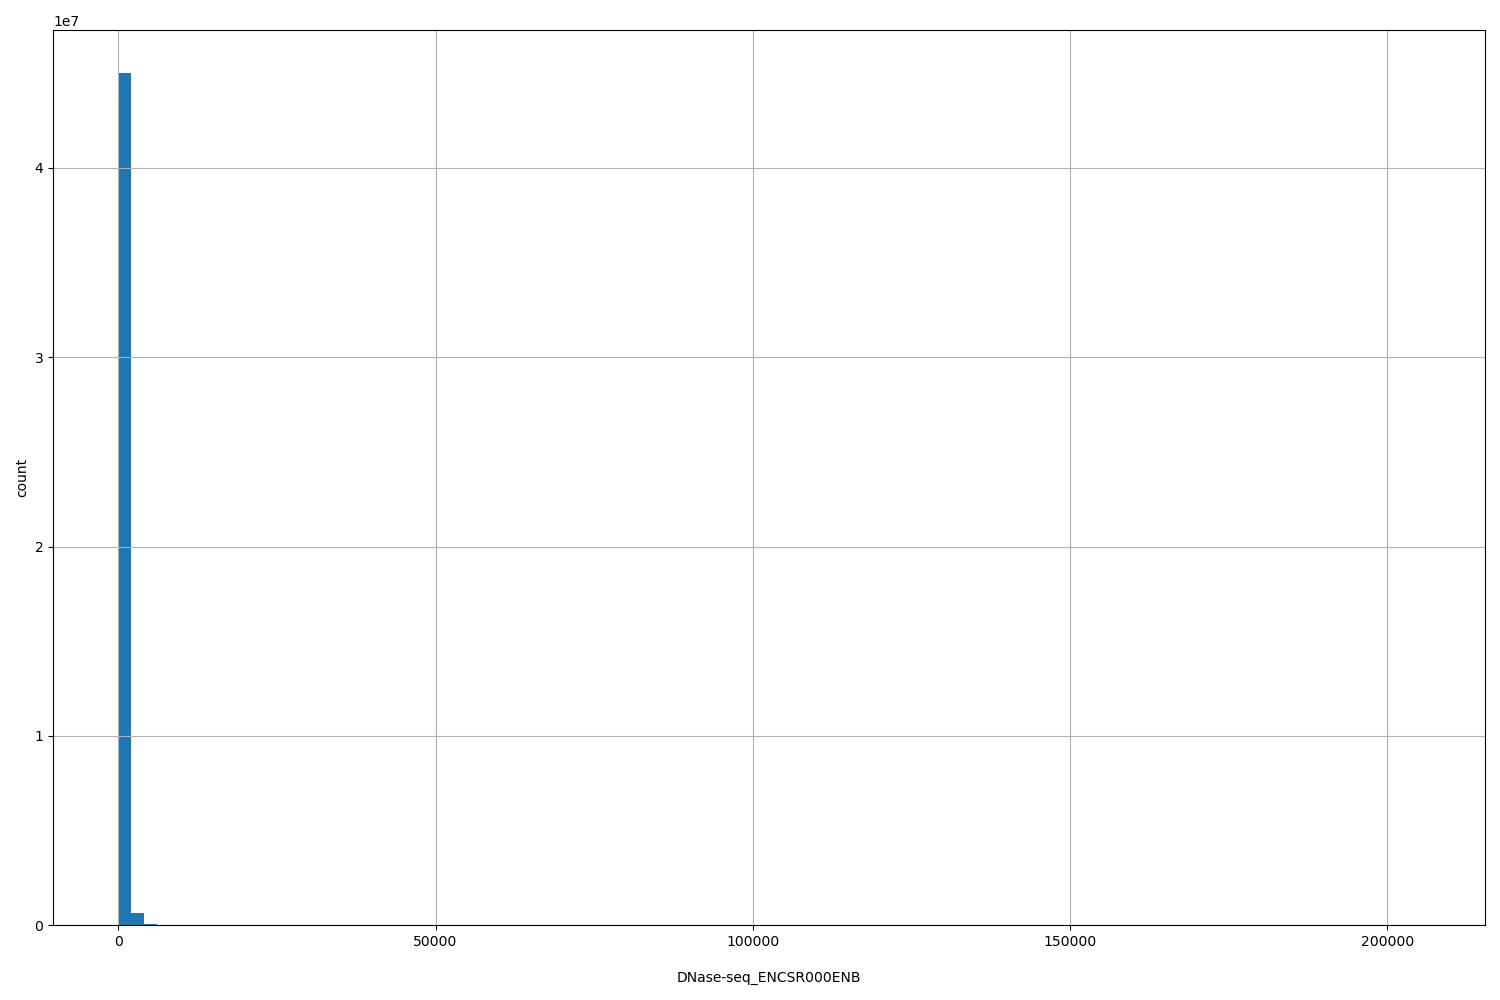 |
[2, 2.05e+05] |
|
n counts base pairs; sd is the population standard deviation.
Coverage
| Chromosome | Covered positions | Covered % | Segments |
|---|---|---|---|
| all chromosomes | 45717881 | 1.42% | 304359 |
| chr1 | 3952187 | 1.59% | 26317 |
| chr2 | 3913906 | 1.62% | 26040 |
| chr3 | 3200463 | 1.61% | 21298 |
| chr4 | 2741871 | 1.44% | 18251 |
| chr5 | 2832071 | 1.56% | 18855 |
| chr6 | 2868817 | 1.68% | 19108 |
| chr7 | 2412826 | 1.51% | 16056 |
| chr8 | 2244329 | 1.55% | 14946 |
| chr9 | 1955542 | 1.41% | 13023 |
| chr10 | 2142465 | 1.60% | 14266 |
| chr11 | 2173882 | 1.61% | 14473 |
| chr12 | 2239656 | 1.68% | 14911 |
| chr13 | 1471746 | 1.29% | 9801 |
| chr14 | 1379071 | 1.29% | 9180 |
| chr15 | 1459979 | 1.43% | 9715 |
| chr16 | 1246850 | 1.38% | 8295 |
| chr17 | 1622592 | 1.95% | 10809 |
| chr18 | 1166348 | 1.45% | 7766 |
| chr19 | 1026424 | 1.75% | 6835 |
| chr20 | 1035050 | 1.61% | 6898 |
| chr21 | 551343 | 1.18% | 3672 |
| chr22 | 641166 | 1.26% | 4268 |
| chrX | 1421897 | 0.91% | 9460 |
| chrY | 17400 | 0.03% | 116 |
| 3342 contigs with no values (129077085 bp) | 0 | 0.00% | 0 |
Segment lengths
| segments | min | max | mean | median | |
|---|---|---|---|---|---|
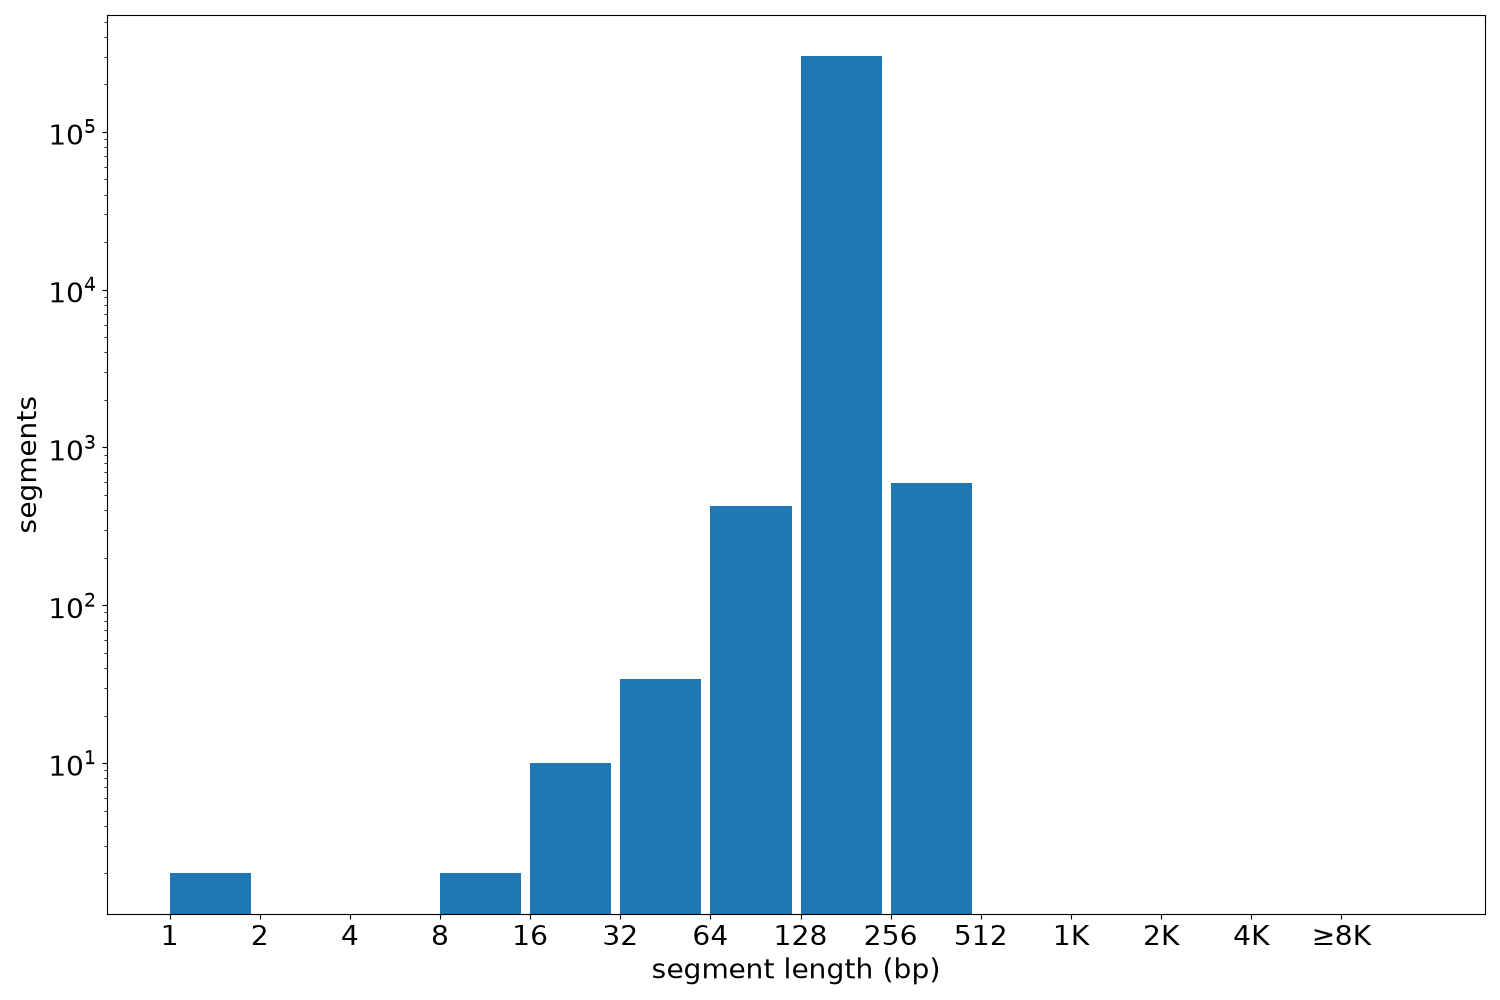
| segments | 304359 | 1 | 450 | 150.21 | 150 |
Files
| Filename | Size | md5 |
|---|---|---|
| ENCFF639MUE.bed.gz | 2.9 MB | d8e917934b2081b727931646a7a0f361 |
| ENCFF639MUE.tabix.bed.gz | 2.5 MB | 6fbbf0dd814053ebacaeb0316aa47e9f |
| ENCFF639MUE.tabix.bed.gz.tbi | 787.18 KB | dd67134c20c16cf0fca8aeeda1b47273 |
| genomic_resource.yaml | 1.94 KB | dcb86c44203ccbdb24c7fe8924e268e4 |
| statistics/ |